option
Home
Flash News
Content
WillGarcía
WillGarcía
August 21, 2026

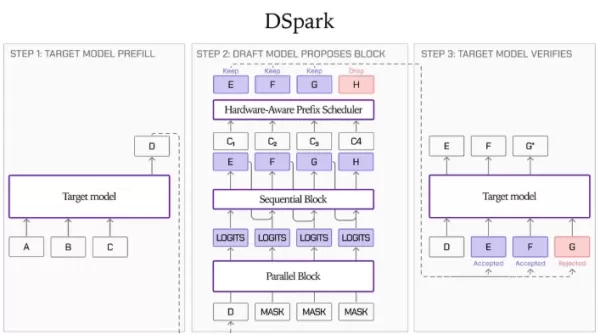
Liquid AI and Hugging Face have released DSpark draft model checkpoints for the three LFM2.5 series models, featuring a speculative decoding path that boosts inference throughput by up to 3.18 times on GPUs and 2.87 times on edge devices without affecting output quality. It cuts LFM2.5-2.6B’s function call latency by 57% in edge agent scenarios, reaching 139 tokens per second on M4Max MacBook Pro, lowering local deployment barriers and offering better performance than some proprietary cloud models. The technology addresses memory bandwidth constraints in traditional inference by using a lightweight draft model to generate candidate tokens, which are validated uniformly. It consists of a parallel backbone network, a sequential head, and a confidence scheduling validator. The initial draft model uses an attention-only 5-layer 9-block architecture with around 300 million parameters. Output accuracy remains unchanged from baseline greedy decoding. DSpark is compatible with SGLang and llama.cpp at launch.
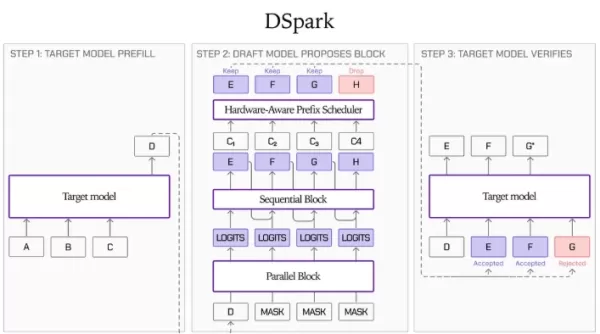
Liquid AI and Hugging Face have released DSpark draft model checkpoints for the three LFM2.5 series models, featuring a speculative decoding path that boosts inference throughput by up to 3.18 times on GPUs and 2.87 times on edge devices without affecting output quality. It cuts LFM2.5-2.6B’s function call latency by 57% in edge agent scenarios, reaching 139 tokens per second on M4Max MacBook Pro, lowering local deployment barriers and offering better performance than some proprietary cloud models. The technology addresses memory bandwidth constraints in traditional inference by using a lightweight draft model to generate candidate tokens, which are validated uniformly. It consists of a parallel backbone network, a sequential head, and a confidence scheduling validator. The initial draft model uses an attention-only 5-layer 9-block architecture with around 300 million parameters. Output accuracy remains unchanged from baseline greedy decoding. DSpark is compatible with SGLang and llama.cpp at launch. Liquid AI and Hugging Face have released DSpark draft model checkpoints for the three LFM2.5 series models, featuring a speculative decoding path that boosts inference throughput by up to 3.18 times on GPUs and 2.87 times on edge devices without affecting output quality. It cuts LFM2.5-2.6B’s function call latency by 57% in edge agent scenarios, reaching 139 tokens per second on M4Max MacBook Pro, lowering local deployment barriers and offering better performance than some proprietary cloud models. The technology addresses memory bandwidth constraints in traditional inference by using a lightweight draft model to generate candidate tokens, which are validated uniformly. It consists of a parallel backbone network, a sequential head, and a confidence scheduling validator. The initial draft model uses an attention-only 5-layer 9-block architecture with around 300 million parameters. Output accuracy remains unchanged from baseline greedy decoding. DSpark is compatible with SGLang and llama.cpp at launch.
Comments (0)
0/300
OR