


 Home
Ant Group Open Sources LingBot-Vision, Giving Robots Spatial Awareness
In embodied intelligence, enabling robots to perceive physical space with human-like precision remains a fundamental challenge. Robbyant, an Ant Group subsidiary specializing in embodied AI, has officially open-sourced the LingBot-Vision model family. This suite of self-supervised vision Transformers achieves exceptional results in dense spatial perception through an innovative "boundary modeling" strategy, outperforming larger models across multiple benchmarks despite having fewer parameters.
Most current visual foundation models prioritize "object recognition," focusing on identifying what is in an image while often overlooking critical physical interaction cues like object boundaries, contours, and depth. LingBot-Vision inverts this approach by treating "boundaries" as primary pre-training signals. By leveraging mask boundary modeling, the model identifies the most information-dense regions in an image and centers its training on them. This method allows the model to acquire semantic understanding while simultaneously developing robust geometric spatial perception.
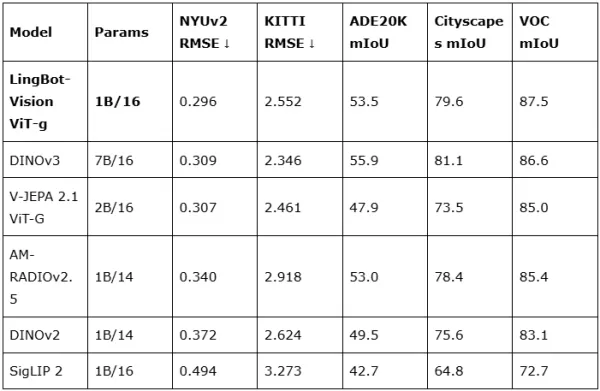
Regarding performance, the flagship LingBot-Vision model, ViT-g/16, contains only 1.1 billion parameters yet achieves state-of-the-art results in depth estimation tasks, including NYU-Depth v2. It surpasses DINOv3, which has 7 billion parameters, while using a training dataset roughly one-third the size. For resource-constrained deployment scenarios, the series offers distilled versions ranging from 3 billion parameters down to smaller sizes, ensuring top-tier dense prediction performance across various hardware configurations.
To showcase the technology's practical value, the development team also upgraded the depth completion system to LingBot-Depth 2.0. Tests indicate significant accuracy improvements when handling transparent objects, a traditional perception blind spot. As data volume increases, LingBot-Vision's performance continues to scale without the saturation typical of traditional models, further validating the potential of its boundary-centric spatial perception architecture in complex real-world environments.
LingBot-Vision is now fully open-sourced on Hugging Face under the Apache-2.0 license, including weights and inference code for four model sizes, from large to small. This technology empowers developers to equip robots with more sensitive physical perception capabilities at lower computational costs, paving the way for a more precise and interactive future in embodied intelligence.
Related article
 Universal Music, ElevenLabs Forge Co-Created AI Music Platform for Fans and Artists
Universal Music Group (UMG) announced on the 10th (US time) that it has entered into a multi-year licensing agreement and a broader strategic partnership with ElevenLabs, an AI audio research and product company. This marks ElevenLabs' first collabor
How does Yahoo Japan SEO ranking work in 2024?
AI-powered image search has evolved from a novelty into a daily essential for millions, yet most users operate under outdated assumptions.The disconnect between what this technology actually achieves and public perception is surprisingly vast.While A
Zuckerberg expands Meta’s enterprise AI vision beyond agents
In June, Meta launched a new AI agent for enterprises, designed to assist with customer service, support, and daily operations. However, CEO Mark Zuckerberg revealed to investors on Wednesday’s second-quarter earnings call that the company’s enterpri
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
In embodied intelligence, enabling robots to perceive physical space with human-like precision remains a fundamental challenge. Robbyant, an Ant Group subsidiary specializing in embodied AI, has officially open-sourced the LingBot-Vision model family. This suite of self-supervised vision Transformers achieves exceptional results in dense spatial perception through an innovative "boundary modeling" strategy, outperforming larger models across multiple benchmarks despite having fewer parameters.
Most current visual foundation models prioritize "object recognition," focusing on identifying what is in an image while often overlooking critical physical interaction cues like object boundaries, contours, and depth. LingBot-Vision inverts this approach by treating "boundaries" as primary pre-training signals. By leveraging mask boundary modeling, the model identifies the most information-dense regions in an image and centers its training on them. This method allows the model to acquire semantic understanding while simultaneously developing robust geometric spatial perception.
Regarding performance, the flagship LingBot-Vision model, ViT-g/16, contains only 1.1 billion parameters yet achieves state-of-the-art results in depth estimation tasks, including NYU-Depth v2. It surpasses DINOv3, which has 7 billion parameters, while using a training dataset roughly one-third the size. For resource-constrained deployment scenarios, the series offers distilled versions ranging from 3 billion parameters down to smaller sizes, ensuring top-tier dense prediction performance across various hardware configurations.
To showcase the technology's practical value, the development team also upgraded the depth completion system to LingBot-Depth 2.0. Tests indicate significant accuracy improvements when handling transparent objects, a traditional perception blind spot. As data volume increases, LingBot-Vision's performance continues to scale without the saturation typical of traditional models, further validating the potential of its boundary-centric spatial perception architecture in complex real-world environments.
LingBot-Vision is now fully open-sourced on Hugging Face under the Apache-2.0 license, including weights and inference code for four model sizes, from large to small. This technology empowers developers to equip robots with more sensitive physical perception capabilities at lower computational costs, paving the way for a more precise and interactive future in embodied intelligence.








 Universal Music, ElevenLabs Forge Co-Created AI Music Platform for Fans and Artists
Universal Music Group (UMG) announced on the 10th (US time) that it has entered into a multi-year licensing agreement and a broader strategic partnership with ElevenLabs, an AI audio research and product company. This marks ElevenLabs' first collabor
How does Yahoo Japan SEO ranking work in 2024?
AI-powered image search has evolved from a novelty into a daily essential for millions, yet most users operate under outdated assumptions.The disconnect between what this technology actually achieves and public perception is surprisingly vast.While A
 Zuckerberg expands Meta’s enterprise AI vision beyond agents
In June, Meta launched a new AI agent for enterprises, designed to assist with customer service, support, and daily operations. However, CEO Mark Zuckerberg revealed to investors on Wednesday’s second-quarter earnings call that the company’s enterpri

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












