


 Home
Google and NVIDIA Open-Source DiffusionGemma, Speeds Up Single-Card Inference by 4x
On June 10, 2026, Google launched DiffusionGemma, an experimental open-source language model that breaks from the traditional autoregressive paradigm of generating text one word at a time. It pioneers the use of diffusion mechanisms from image AI in text generation, starting from random noise and refining iteratively to output 256 token blocks in parallel per step.
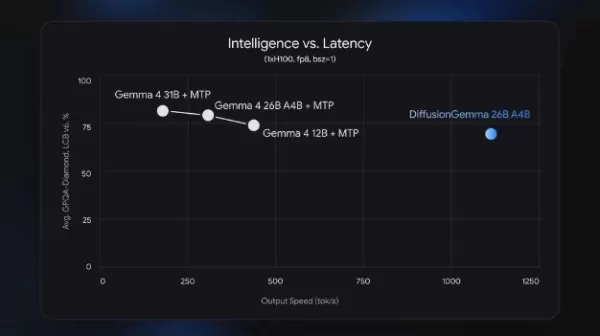
In terms of hardware performance, NVIDIA's deep optimizations enable the model to run nearly four times faster than comparable traditional models in single‑GPU single‑user mode. On an H100 GPU, it achieves output speeds of up to 1,000 tokens per second for a single request, and even on high‑end consumer GPUs like the RTX 5090 it can exceed 700 tokens per second.
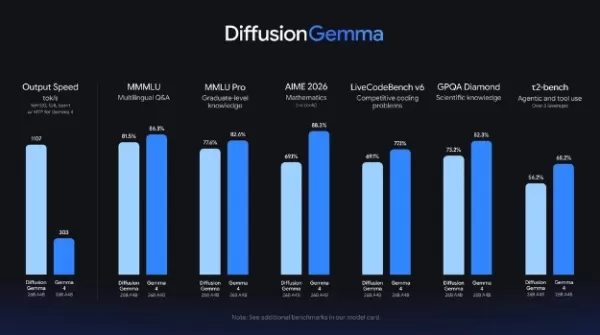
DiffusionGemma has 26 billion parameters and uses a mixture‑of‑experts (MoE) architecture, activating only 3.8 billion parameters per step. While its text generation quality and accuracy slightly trail traditional Gemma4 series models on standard benchmarks, its unique “full‑block awareness” overcomes the backward‑only limitation of autoregressive models. Because all tokens can reference each other during generation, it excels in tasks involving nonlinear and structured data, such as text completion, code filling, Sudoku solving, and amino acid sequence processing.
The model weights are now open‑sourced on Hugging Face under the Apache 2.0 license and work seamlessly with mainstream inference frameworks like vLLM and MLX. This exploration not only removes memory bandwidth constraints on GPU compute power but also opens a new technical path for future AI applications in complex logic and nonlinear text generation.
Related article
 ByteDance Boosts Core AI Incentives as Doubao Surges 14.6%
ByteDance recently convened a DouBao equity briefing to unveil fresh incentive policies for staff involved in the DouBao division. The strike price for DouBao shares has been lifted from $14.85 in June 2026 to $17.02, marking an approximate 14.6% inc
MiniMax Unveils 10x Team Program to Incentivize Global AI Experts
MiniMax (Xiyu Technology), the General Artificial Intelligence Lab, has officially launched "10x Team," a global talent collaboration initiative. This program aims to recruit top experts across industries to explore the deep application of large mode
South Korea Breaks Ground on National AI Computing Center, Investing 2.5 Trillion Won with 2028 Target
South Korean outlet EtNews reports that groundbreaking for the Korea AI Computing Center (KOACC) took place on August 3 at the Solar City data center park in Sunan, Jeollanam-do. Backed by a total investment of 2.5 trillion KRW (roughly 11.838 billio
Related Special Topic Recommendations
Education and Learning
 AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
 10 tools
 xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai
Education and Learning
AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs
2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai

 Comments (0)
0/500
On June 10, 2026, Google launched DiffusionGemma, an experimental open-source language model that breaks from the traditional autoregressive paradigm of generating text one word at a time. It pioneers the use of diffusion mechanisms from image AI in text generation, starting from random noise and refining iteratively to output 256 token blocks in parallel per step.
In terms of hardware performance, NVIDIA's deep optimizations enable the model to run nearly four times faster than comparable traditional models in single‑GPU single‑user mode. On an H100 GPU, it achieves output speeds of up to 1,000 tokens per second for a single request, and even on high‑end consumer GPUs like the RTX 5090 it can exceed 700 tokens per second.
DiffusionGemma has 26 billion parameters and uses a mixture‑of‑experts (MoE) architecture, activating only 3.8 billion parameters per step. While its text generation quality and accuracy slightly trail traditional Gemma4 series models on standard benchmarks, its unique “full‑block awareness” overcomes the backward‑only limitation of autoregressive models. Because all tokens can reference each other during generation, it excels in tasks involving nonlinear and structured data, such as text completion, code filling, Sudoku solving, and amino acid sequence processing.
The model weights are now open‑sourced on Hugging Face under the Apache 2.0 license and work seamlessly with mainstream inference frameworks like vLLM and MLX. This exploration not only removes memory bandwidth constraints on GPU compute power but also opens a new technical path for future AI applications in complex logic and nonlinear text generation.








 ByteDance Boosts Core AI Incentives as Doubao Surges 14.6%
ByteDance recently convened a DouBao equity briefing to unveil fresh incentive policies for staff involved in the DouBao division. The strike price for DouBao shares has been lifted from $14.85 in June 2026 to $17.02, marking an approximate 14.6% inc
 MiniMax Unveils 10x Team Program to Incentivize Global AI Experts
MiniMax (Xiyu Technology), the General Artificial Intelligence Lab, has officially launched "10x Team," a global talent collaboration initiative. This program aims to recruit top experts across industries to explore the deep application of large mode
 South Korea Breaks Ground on National AI Computing Center, Investing 2.5 Trillion Won with 2028 Target
South Korean outlet EtNews reports that groundbreaking for the Korea AI Computing Center (KOACC) took place on August 3 at the Solar City data center park in Sunan, Jeollanam-do. Backed by a total investment of 2.5 trillion KRW (roughly 11.838 billio

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai












