


 Home
Global First Event-Level Embodied Intelligence World Model Ends Frame-by-Frame Learning for Robots
On May 29, the Variable Robot team unveiled WALL-WM, the world’s first embodied intelligence world model built on “event-level prediction.” This model breaks free from conventional embodied large models that learn actions frame by frame over time, instead switching the world model’s prediction unit to semantic events. It marks a new stage in how robots understand and carry out tasks.
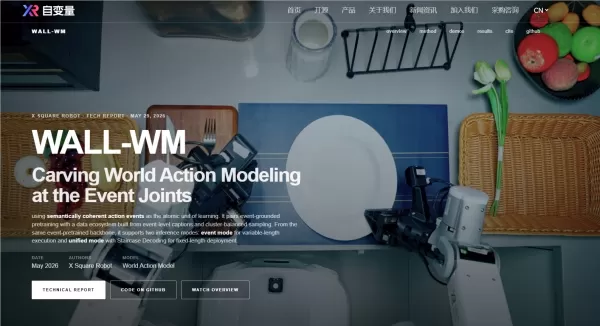
In the current embodied intelligence industry, mainstream vision-language-action (VLA) models typically take a current image and instruction to predict a fixed-length action block. This frame-by-frame training approach often causes robots to focus on minor physical movements while losing sight of the action’s ultimate goal. When faced with scenarios like changing cups or tables, robots frequently fail due to a lack of generalization. To address this industry pain point, the Variable team pointed out in their academic paper that text, vision, and action information naturally exist at different time scales and manifold geometries in the real world. Forcing them into a single shared space can easily damage the pre-trained geometric prior.
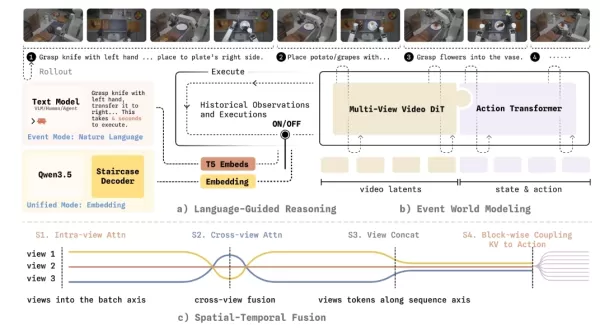
To tackle this challenge, the WALL-WM world model introduces an innovative event-centered training and execution mechanism. It breaks down complex tasks into semantically clear event joints, such as reaching, grasping, and moving. In operation, the model no longer rigidly computes the next image frame. Instead, it first simulates how the world will change due to the next event, then precisely translates that visual change into the robotic arm’s motion trajectory.
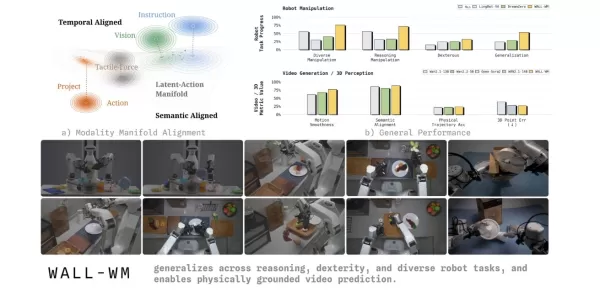
To ensure this new architecture can be reliably deployed in the physical world, the Variable Robot team carried out a series of hardcore engineering overhauls. The system supports flexible switching between “event mode” (with variable-length action output) and “unified mode” (with real-time closed-loop control) on the same base weights. It also achieves one-way coupling between video models and action models, preventing valuable dynamic priors from internet videos from being prematurely biased by action data. For geometric perception across multiple cameras, the model introduces frustum masks and tubular masks, forcing the AI to develop cross-view true three-dimensional geometric correspondence. To address decision latency, it employs a new “stepped chain-of-thought decoding” technique that significantly reduces decoding delay while maintaining logical interpretability.
Related article
 How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust
Slackbot Becomes an AI Agent
Slackbot, the automated assistant embedded in Salesforce’s corporate messaging platform Slack, is evolving into an AI agent. Salesforce CTO Parker Harris envisions it achieving viral status comparable to OpenAI’s ChatGPT.The cloud software giant laun
ByteDance Boosts Core AI Incentives as Doubao Surges 14.6%
ByteDance recently convened a DouBao equity briefing to unveil fresh incentive policies for staff involved in the DouBao division. The strike price for DouBao shares has been lifted from $14.85 in June 2026 to $17.02, marking an approximate 14.6% inc
Related Special Topic Recommendations
Education and Learning
 AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
 10 tools
 xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai
Education and Learning
AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs
2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai

 Comments (1)
0/500
![JasonHarris]()
Finally, a model that doesn't just process frames like a slow-motion video player! 🤖 This event-level prediction sounds way more efficient for real-time robot actions. I've been waiting for something that breaks free from the traditional frame-by-frame bottleneck. Can't wait to see how WALL-WM handles unpredictable environments. #AI #Robotics
On May 29, the Variable Robot team unveiled WALL-WM, the world’s first embodied intelligence world model built on “event-level prediction.” This model breaks free from conventional embodied large models that learn actions frame by frame over time, instead switching the world model’s prediction unit to semantic events. It marks a new stage in how robots understand and carry out tasks.
In the current embodied intelligence industry, mainstream vision-language-action (VLA) models typically take a current image and instruction to predict a fixed-length action block. This frame-by-frame training approach often causes robots to focus on minor physical movements while losing sight of the action’s ultimate goal. When faced with scenarios like changing cups or tables, robots frequently fail due to a lack of generalization. To address this industry pain point, the Variable team pointed out in their academic paper that text, vision, and action information naturally exist at different time scales and manifold geometries in the real world. Forcing them into a single shared space can easily damage the pre-trained geometric prior.
To tackle this challenge, the WALL-WM world model introduces an innovative event-centered training and execution mechanism. It breaks down complex tasks into semantically clear event joints, such as reaching, grasping, and moving. In operation, the model no longer rigidly computes the next image frame. Instead, it first simulates how the world will change due to the next event, then precisely translates that visual change into the robotic arm’s motion trajectory.
To ensure this new architecture can be reliably deployed in the physical world, the Variable Robot team carried out a series of hardcore engineering overhauls. The system supports flexible switching between “event mode” (with variable-length action output) and “unified mode” (with real-time closed-loop control) on the same base weights. It also achieves one-way coupling between video models and action models, preventing valuable dynamic priors from internet videos from being prematurely biased by action data. For geometric perception across multiple cameras, the model introduces frustum masks and tubular masks, forcing the AI to develop cross-view true three-dimensional geometric correspondence. To address decision latency, it employs a new “stepped chain-of-thought decoding” technique that significantly reduces decoding delay while maintaining logical interpretability.








 How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust
 Slackbot Becomes an AI Agent
Slackbot, the automated assistant embedded in Salesforce’s corporate messaging platform Slack, is evolving into an AI agent. Salesforce CTO Parker Harris envisions it achieving viral status comparable to OpenAI’s ChatGPT.The cloud software giant laun
 ByteDance Boosts Core AI Incentives as Doubao Surges 14.6%
ByteDance recently convened a DouBao equity briefing to unveil fresh incentive policies for staff involved in the DouBao division. The strike price for DouBao shares has been lifted from $14.85 in June 2026 to $17.02, marking an approximate 14.6% inc

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai

Finally, a model that doesn't just process frames like a slow-motion video player! 🤖 This event-level prediction sounds way more efficient for real-time robot actions. I've been waiting for something that breaks free from the traditional frame-by-frame bottleneck. Can't wait to see how WALL-WM handles unpredictable environments. #AI #Robotics












