


 Home
ByteDance Seedance 2.5 Unveiled: 30-Second Single-Take AI Video That Tells a Story
ByteDance has officially released Seedance 2.5, a video generation model that doubles the maximum output duration from 15 to 30 seconds per video. The platform will roll out gradually on Ji Meng AI and Dou Bao Professional Edition, with API integration into Volcano Argo planned soon to support diverse applications in film, advertising, education, industrial manufacturing, and autonomous driving.
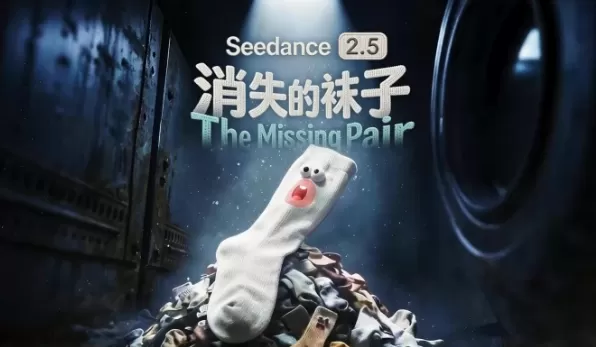
According to the official announcement, Seedance 2.5 retains its unified multimodal audio-visual architecture while delivering significant upgrades in long-form narrative, multimodal referencing, and editing precision. This advancement allows AI-generated videos to transition from isolated clips to cohesive stories with clear beginnings, middles, and endings.
Seamless multi-shot storytelling within 30 seconds, ensuring consistency through extended generation
Official demonstrations highlight the model’s ability to structure complex narratives within a 30-second window. One example features a singer’s performance, tracking the camera from behind red curtains to a backstage dressing room. The sequence captures the singer adjusting her earphones, receiving stage cues, walking through a corridor, interacting with a partner, and finally stepping onto the stage. The camera pulls back to reveal the full stadium, including the audience, lighting, and cheering crowds. The model successfully organizes logically connected shots—setup, development, climax, and resolution—within the time limit.
The model’s multi-round extension feature is equally robust, allowing it to generate an additional 30 seconds of video based on existing footage. It maintains consistency in characters, settings, visual style, and audio effects. In one demo, a boy exits a subway car with a soccer ball, pursued by a man who eventually catches him. The continuous action flows seamlessly without visual or narrative breaks.
Process up to 30 images and 10 videos simultaneously for complex group narratives
Seedance 2.5 allows users to upload up to 30 images, 10 video clips, and 10 audio files as reference inputs. The model analyzes composition, scenes, styles, characters, and props across these materials, applying them accurately according to user instructions. In multi-character scenes, it preserves the appearance and voice of each individual while keeping the main subject stable. A 30-second concert clip demonstrated this capability, using a 16:9 cinematic format with references including a pianist, cellist, violinist, vocalist, orchestra, choir, and audience. As AI video tools evolve from simple effects generators to comprehensive narrative platforms, the workflow for short video production may require a complete overhaul.
Related article
 Amazon to Acquire Decart for $7B, Securing Key AI Chip Adapter
Per the Wall Street Journal, Amazon is negotiating to purchase AI startup Decart at an estimated $7 billion valuation. If no competing bids arise, the transaction could close shortly, underscoring major tech firms’ urgency to secure computing resourc
How Locus tackles one of robotics' biggest challenges: manipulation
NeuraGrasp handles diverse items, including small containers, porous polybags, and textiles. | Source: Locus RoboticsLocus Robotics Corp. has solved numerous robotic hurdles in live operational settings. Its autonomous mobile robots (AMRs) have trave
McKinsey warns 11 million Americans face job shifts or career changes as AI reshapes the workforce
McKinsey’s September 29 report on AI and employment highlights a critical challenge: not job displacement, but the massive task of redeploying millions of workers into new roles.By 2035, an estimated 11 million U.S. workers—roughly 7% of the current
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
ByteDance has officially released Seedance 2.5, a video generation model that doubles the maximum output duration from 15 to 30 seconds per video. The platform will roll out gradually on Ji Meng AI and Dou Bao Professional Edition, with API integration into Volcano Argo planned soon to support diverse applications in film, advertising, education, industrial manufacturing, and autonomous driving.
According to the official announcement, Seedance 2.5 retains its unified multimodal audio-visual architecture while delivering significant upgrades in long-form narrative, multimodal referencing, and editing precision. This advancement allows AI-generated videos to transition from isolated clips to cohesive stories with clear beginnings, middles, and endings.
Seamless multi-shot storytelling within 30 seconds, ensuring consistency through extended generation
Official demonstrations highlight the model’s ability to structure complex narratives within a 30-second window. One example features a singer’s performance, tracking the camera from behind red curtains to a backstage dressing room. The sequence captures the singer adjusting her earphones, receiving stage cues, walking through a corridor, interacting with a partner, and finally stepping onto the stage. The camera pulls back to reveal the full stadium, including the audience, lighting, and cheering crowds. The model successfully organizes logically connected shots—setup, development, climax, and resolution—within the time limit.
The model’s multi-round extension feature is equally robust, allowing it to generate an additional 30 seconds of video based on existing footage. It maintains consistency in characters, settings, visual style, and audio effects. In one demo, a boy exits a subway car with a soccer ball, pursued by a man who eventually catches him. The continuous action flows seamlessly without visual or narrative breaks.
Process up to 30 images and 10 videos simultaneously for complex group narratives
Seedance 2.5 allows users to upload up to 30 images, 10 video clips, and 10 audio files as reference inputs. The model analyzes composition, scenes, styles, characters, and props across these materials, applying them accurately according to user instructions. In multi-character scenes, it preserves the appearance and voice of each individual while keeping the main subject stable. A 30-second concert clip demonstrated this capability, using a 16:9 cinematic format with references including a pianist, cellist, violinist, vocalist, orchestra, choir, and audience. As AI video tools evolve from simple effects generators to comprehensive narrative platforms, the workflow for short video production may require a complete overhaul.








 Amazon to Acquire Decart for $7B, Securing Key AI Chip Adapter
Per the Wall Street Journal, Amazon is negotiating to purchase AI startup Decart at an estimated $7 billion valuation. If no competing bids arise, the transaction could close shortly, underscoring major tech firms’ urgency to secure computing resourc
How Locus tackles one of robotics' biggest challenges: manipulation
NeuraGrasp handles diverse items, including small containers, porous polybags, and textiles. | Source: Locus RoboticsLocus Robotics Corp. has solved numerous robotic hurdles in live operational settings. Its autonomous mobile robots (AMRs) have trave
McKinsey warns 11 million Americans face job shifts or career changes as AI reshapes the workforce
McKinsey’s September 29 report on AI and employment highlights a critical challenge: not job displacement, but the massive task of redeploying millions of workers into new roles.By 2035, an estimated 11 million U.S. workers—roughly 7% of the current

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












