


 Home
Mistral unveils open-source speech generation model
French AI company Mistral unveiled a new open-source text-to-speech model on Thursday, designed for voice AI assistants and enterprise applications like customer support. The model enables businesses to build voice agents for sales and customer engagement, positioning Mistral as a direct competitor to ElevenLabs, Deepgram, and OpenAI.
Called Voxtral TTS, the model supports nine languages, including English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, and Arabic.
"Our customers have been asking for a speech model. So we built a small-sized speech model that can fit on a smartwatch, a smartphone, a laptop, or other edge devices. The cost is a fraction of anything else on the market, yet it delivers state-of-the-art performance," said Pierre Stock, VP of science operations at Mistral AI, in a phone interview with TechCrunch.
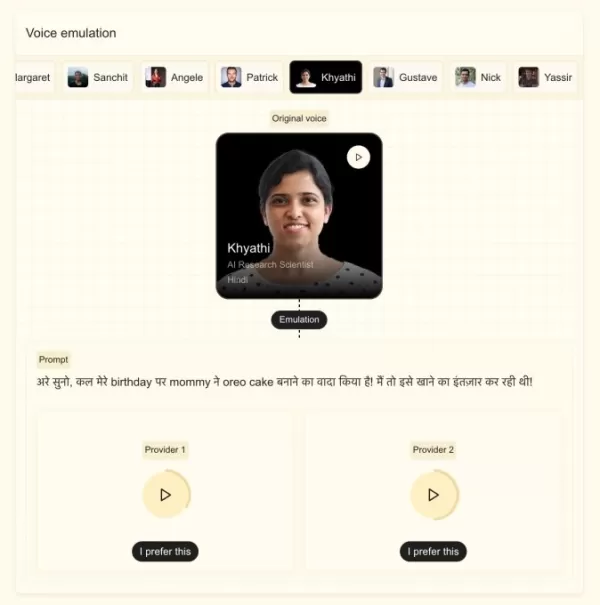
Image credit: Mistral
Mistral states the new model can adapt to a custom voice using a sample shorter than five seconds, capturing subtle accents, inflections, intonations, and irregularities in speech flow. Built on Ministral 3B, it can switch between languages smoothly while preserving voice characteristics, making it ideal for dubbing or real-time translation. Stock noted the company aimed to make the model sound human, not robotic.
According to the company, the model is built for real-time performance. Its time-to-first-audio (TTFA) — the time between receiving input and beginning to 'speak' — is 90ms for a 10-second sample of 500 characters. The model also achieves a real-time factor (RTF) of 6x, meaning it can generate a 10-second clip in roughly 1.6 seconds.
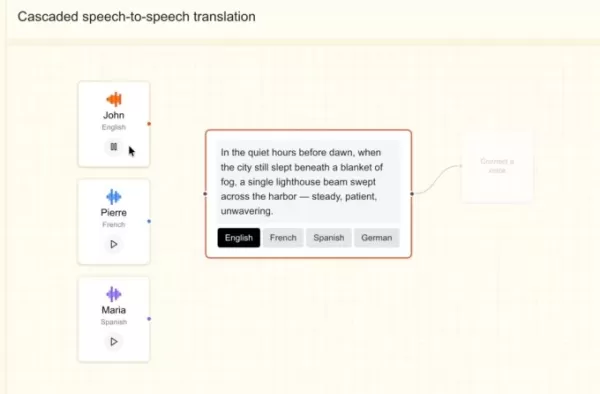
Image credit: Mistral AI
Earlier this year, Mistral launched two transcription models — one for large-scale batch processing, the other for low-latency real-time use cases. With the new speech model, the company appears to be building a comprehensive suite of voice products for enterprises.
Stock added, "We plan to create an end-to-end platform capable of handling multimodal input streams — audio, text, and image — as well as output. The key advantage is that an end-to-end agentic system supporting audio input and output provides much richer information."
Mistral positions its open-source nature and customization capabilities as key differentiators, allowing enterprises to tune the model to their specific needs, thus favoring it over competitor solutions.
Related article
 ElevenLabs Unveils Music AI That Switches Genres Mid-Song
ElevenLabs, a voice AI company, has launched Music v2, the latest version of its music-generation model, which can shift genres mid-track. The model is designed to handle complex vocals and composition. This release comes nearly ten months after the
Google rolls out voice-based prompts in Docs and Keep
At the Google I/O developer conference, the company announced it's introducing voice-based prompting to Workspace apps like Docs, Keep, and Gmail. These capabilities let users create drafts, take notes, and search for emails using voice.In Docs, you
Ex-Goldman, Meta founders build voice AI for overlooked markets
Customer support and service are among the hottest areas in voice AI today. But building a product that sounds human and responds with minimal delay is far more challenging in some markets than in others — and most major players weren’t designed with
Related Special Topic Recommendations
Music composition
 AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
 9 tools
 xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai
Education and Learning
AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs
2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai
code
AI Pull Request Review Tools for GitHub Teams Handling Refactors, Bugs, and Security Gaps
2026 Latest Best AI Pull Request Review Tools for GitHub Teams are here on XIX.AI! This top-rated curated list showcases powerful game-changing solutions that streamline refactoring, bug fixing, and security gap detection across all team workflows. Enjoy a free vs paid comparison along with real-world tests and detailed rankings to help you find the perfect tool that boosts productivity significantly. Explore now to unlock your AI edge!
12 tools
xix.ai

 Comments (1)
0/500
![WilliamRamirez]()
I just tried out Mistral’s new open-source TTS model yesterday, and its pronunciation is way more natural than most free options I’ve used before. It’s super useful for companies that want to build their own voice assistants without spending tons on licensed services. Do you think this will change the game in the enterprise voice AI market?
French AI company Mistral unveiled a new open-source text-to-speech model on Thursday, designed for voice AI assistants and enterprise applications like customer support. The model enables businesses to build voice agents for sales and customer engagement, positioning Mistral as a direct competitor to ElevenLabs, Deepgram, and OpenAI.
Called Voxtral TTS, the model supports nine languages, including English, French, German, Spanish, Dutch, Portuguese, Italian, Hindi, and Arabic.
"Our customers have been asking for a speech model. So we built a small-sized speech model that can fit on a smartwatch, a smartphone, a laptop, or other edge devices. The cost is a fraction of anything else on the market, yet it delivers state-of-the-art performance," said Pierre Stock, VP of science operations at Mistral AI, in a phone interview with TechCrunch.
Image credit: Mistral
Mistral states the new model can adapt to a custom voice using a sample shorter than five seconds, capturing subtle accents, inflections, intonations, and irregularities in speech flow. Built on Ministral 3B, it can switch between languages smoothly while preserving voice characteristics, making it ideal for dubbing or real-time translation. Stock noted the company aimed to make the model sound human, not robotic.
According to the company, the model is built for real-time performance. Its time-to-first-audio (TTFA) — the time between receiving input and beginning to 'speak' — is 90ms for a 10-second sample of 500 characters. The model also achieves a real-time factor (RTF) of 6x, meaning it can generate a 10-second clip in roughly 1.6 seconds.
Image credit: Mistral AI
Earlier this year, Mistral launched two transcription models — one for large-scale batch processing, the other for low-latency real-time use cases. With the new speech model, the company appears to be building a comprehensive suite of voice products for enterprises.
Stock added, "We plan to create an end-to-end platform capable of handling multimodal input streams — audio, text, and image — as well as output. The key advantage is that an end-to-end agentic system supporting audio input and output provides much richer information."
Mistral positions its open-source nature and customization capabilities as key differentiators, allowing enterprises to tune the model to their specific needs, thus favoring it over competitor solutions.








 ElevenLabs Unveils Music AI That Switches Genres Mid-Song
ElevenLabs, a voice AI company, has launched Music v2, the latest version of its music-generation model, which can shift genres mid-track. The model is designed to handle complex vocals and composition. This release comes nearly ten months after the
 Google rolls out voice-based prompts in Docs and Keep
At the Google I/O developer conference, the company announced it's introducing voice-based prompting to Workspace apps like Docs, Keep, and Gmail. These capabilities let users create drafts, take notes, and search for emails using voice.In Docs, you
 Ex-Goldman, Meta founders build voice AI for overlooked markets
Customer support and service are among the hottest areas in voice AI today. But building a product that sounds human and responds with minimal delay is far more challenging in some markets than in others — and most major players weren’t designed with

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai

2026 Latest Best AI Pull Request Review Tools for GitHub Teams are here on XIX.AI! This top-rated curated list showcases powerful game-changing solutions that streamline refactoring, bug fixing, and security gap detection across all team workflows. Enjoy a free vs paid comparison along with real-world tests and detailed rankings to help you find the perfect tool that boosts productivity significantly. Explore now to unlock your AI edge!
12 tools
xix.ai

I just tried out Mistral’s new open-source TTS model yesterday, and its pronunciation is way more natural than most free options I’ve used before. It’s super useful for companies that want to build their own voice assistants without spending tons on licensed services. Do you think this will change the game in the enterprise voice AI market?












