

 Home
GPT 5.5 Leads AI Security Race, DeepSeek Tops Cost-Efficiency
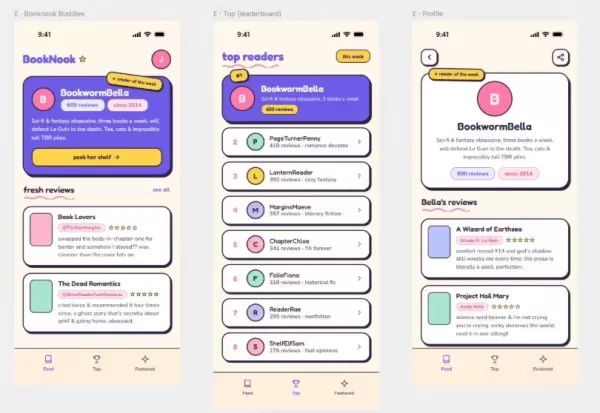
Kasra Rahjerdi, a security researcher, recently published a significant report detailing practical tests on the security reasoning of major large language models. He achieved this by constructing a deliberately vulnerable book review application. In this scenario, which mimics real-world vulnerabilities, Rahjerdi embedded Google mobile backend service credentials within the application file. The models were tasked with unpacking and identifying these credentials to gain direct access to the database.
Comparing Top Models
Operating under strict constraints of a two-hour time limit and a $10 budget, the models exhibited varying levels of performance. GPT-5.5 emerged as the strongest performer, successfully completing 7 out of 10 attempts and leading in success rate. The report notes that GPT-5.5 could quickly locate key credentials after unpacking, ignoring distractions from complex or conventional application interfaces.
Conversely, Gemini’s performance was underwhelming. Gemini 3.1 Pro Preview triggered its built-in safety filters almost immediately at the start of each task, resulting in significantly lower token consumption compared to other tested models.
Evaluating Cost-Effectiveness
Despite GPT-5.5’s high success rate, its average cost per successful run reached $9.46, deterring teams that need to execute tools in bulk. In contrast, DeepSeek V4 Pro distinguished itself through superior cost-efficiency. Although it succeeded in only 3 out of 10 tests, its average cost per successful run was just $0.62.
This indicates that, when calculating the cost per single success, DeepSeek V4 Pro is approximately fifteen times cheaper than GPT-5.5. Even though it occasionally misused a backend authentication interface during failed attempts, this substantial cost advantage offers significant practical value for teams deploying large-scale security testing.
Related article
 SpaceX AI Could Outpace Anthropic Within Half a Year, Musk Says
SpaceXAI CEO Elon Musk predicts AI dominance within six months, leveraging compute hardware to bridge the gap with competitors.SpaceXAI CEO Elon Musk recently stated on X that his company aims to lead the frontier AI landscape within approximately si
WeRide Unveils WITT, a Physical AI Large Model
Autonomous driving technology is advancing at a remarkable pace. On July 17, WeRide, a leading autonomous driving firm, unveiled its proprietary physical AI cognitive foundation model, WeRide WITT. This launch represents a significant milestone in AI
GitHub Copilot Integrates GPT-5.4 in Hours
GitHub Copilot has once again proven its rapid response capabilities. Mere hours after OpenAI launched its newest flagship model, GPT-5.4, GitHub announced full integration, providing developers worldwide with intelligent coding assistance powered by
Related Special Topic Recommendations
Productivity
 Best AI Second-Brain Organizers for Notes and Tasks
2026 Latest Best Top-Rated AI Second-Brain Organizers for Notes and Tasks! XIX.AI has curated a highly powerful game-changing collection, featuring weekly updated rankings, free vs paid comparison, and real-world tests to help you find the perfect tool that boosts productivity dramatically. Explore now to unlock your AI edge!
 11 tools
 xix.ai
Prompt
AI Prompt Testing Platforms for ChatGPT and Claude Workflows
2026 Latest Best Top-Rated AI Prompt Testing Platforms for ChatGPT and Claude Workflows! XIX.AI curates a powerful game-changing collection, featuring weekly updated rankings, free vs paid comparison, real-world tests, and detailed feature breakdowns to help you identify the must-try tools that boost productivity and deliver flawless outputs. Explore now to discover your perfect solution and unlock your AI edge. (249 characters)
9 tools
xix.ai
Marketing
AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion
2026 Latest Best AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion are here on XIX.AI. This curated list of top-rated tools offers powerful game-changing solutions to boost content quality, improve writing efficiency, and enhance overall productivity. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings. Must-try options help you break through creation bottlenecks. Explore now to discover your perfect tool and unlock your AI edge!
8 tools
xix.ai
Finance
Excel AI Budget Forecasting Tools for Cash Flow Planning and Expense Control
2026 Latest Best Excel AI tools for cash flow planning and expense control are here on XIX.AI’s top-rated curated list. These powerful game-changing solutions help you boost productivity significantly through real-world tests and rigorous rankings. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge in financial management.
9 tools
xix.ai
Prompt
AI Prompt Management Tools for Teams
2026 Latest Best Top-Rated AI Prompt Management Tools for Teams are curated by XIX.AI here. This weekly updated guide features powerful game-changing solutions that boost team productivity significantly through real-world tests and detailed rankings. Get a free vs paid comparison to help you choose the perfect tool. Explore now to Unlock your AI edge.
9 tools
xix.ai
Music composition
AI Lyric Idea Tools for Music Composition
2026 Latest Best Top-rated AI Lyric Idea Tools for Music Composition are here on XIX.AI! This curated collection features powerful game-changing options that go through real-world tests to deliver high-quality lyric concepts fast, helping users boost creativity and streamline their music creation process. Get a free vs paid comparison overview too. Explore now to Discover your perfect tool!
16 tools
xix.ai

 Comments (0)
0/500
Kasra Rahjerdi, a security researcher, recently published a significant report detailing practical tests on the security reasoning of major large language models. He achieved this by constructing a deliberately vulnerable book review application. In this scenario, which mimics real-world vulnerabilities, Rahjerdi embedded Google mobile backend service credentials within the application file. The models were tasked with unpacking and identifying these credentials to gain direct access to the database.
Comparing Top Models
Operating under strict constraints of a two-hour time limit and a $10 budget, the models exhibited varying levels of performance. GPT-5.5 emerged as the strongest performer, successfully completing 7 out of 10 attempts and leading in success rate. The report notes that GPT-5.5 could quickly locate key credentials after unpacking, ignoring distractions from complex or conventional application interfaces.
Conversely, Gemini’s performance was underwhelming. Gemini 3.1 Pro Preview triggered its built-in safety filters almost immediately at the start of each task, resulting in significantly lower token consumption compared to other tested models.
Evaluating Cost-Effectiveness
Despite GPT-5.5’s high success rate, its average cost per successful run reached $9.46, deterring teams that need to execute tools in bulk. In contrast, DeepSeek V4 Pro distinguished itself through superior cost-efficiency. Although it succeeded in only 3 out of 10 tests, its average cost per successful run was just $0.62.
This indicates that, when calculating the cost per single success, DeepSeek V4 Pro is approximately fifteen times cheaper than GPT-5.5. Even though it occasionally misused a backend authentication interface during failed attempts, this substantial cost advantage offers significant practical value for teams deploying large-scale security testing.


 SpaceX AI Could Outpace Anthropic Within Half a Year, Musk Says
SpaceXAI CEO Elon Musk predicts AI dominance within six months, leveraging compute hardware to bridge the gap with competitors.SpaceXAI CEO Elon Musk recently stated on X that his company aims to lead the frontier AI landscape within approximately si
 WeRide Unveils WITT, a Physical AI Large Model
Autonomous driving technology is advancing at a remarkable pace. On July 17, WeRide, a leading autonomous driving firm, unveiled its proprietary physical AI cognitive foundation model, WeRide WITT. This launch represents a significant milestone in AI
 GitHub Copilot Integrates GPT-5.4 in Hours
GitHub Copilot has once again proven its rapid response capabilities. Mere hours after OpenAI launched its newest flagship model, GPT-5.4, GitHub announced full integration, providing developers worldwide with intelligent coding assistance powered by
2026 Latest Best Top-Rated AI Second-Brain Organizers for Notes and Tasks! XIX.AI has curated a highly powerful game-changing collection, featuring weekly updated rankings, free vs paid comparison, and real-world tests to help you find the perfect tool that boosts productivity dramatically. Explore now to unlock your AI edge!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Testing Platforms for ChatGPT and Claude Workflows! XIX.AI curates a powerful game-changing collection, featuring weekly updated rankings, free vs paid comparison, real-world tests, and detailed feature breakdowns to help you identify the must-try tools that boost productivity and deliver flawless outputs. Explore now to discover your perfect solution and unlock your AI edge. (249 characters)
9 tools
xix.ai

2026 Latest Best AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion are here on XIX.AI. This curated list of top-rated tools offers powerful game-changing solutions to boost content quality, improve writing efficiency, and enhance overall productivity. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings. Must-try options help you break through creation bottlenecks. Explore now to discover your perfect tool and unlock your AI edge!
8 tools
xix.ai

2026 Latest Best Excel AI tools for cash flow planning and expense control are here on XIX.AI’s top-rated curated list. These powerful game-changing solutions help you boost productivity significantly through real-world tests and rigorous rankings. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge in financial management.
9 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Management Tools for Teams are curated by XIX.AI here. This weekly updated guide features powerful game-changing solutions that boost team productivity significantly through real-world tests and detailed rankings. Get a free vs paid comparison to help you choose the perfect tool. Explore now to Unlock your AI edge.
9 tools
xix.ai

2026 Latest Best Top-rated AI Lyric Idea Tools for Music Composition are here on XIX.AI! This curated collection features powerful game-changing options that go through real-world tests to deliver high-quality lyric concepts fast, helping users boost creativity and streamline their music creation process. Get a free vs paid comparison overview too. Explore now to Discover your perfect tool!
16 tools
xix.ai












