


 Home
Fish Audio Launches S2: Open-Source Model Enables Word-Level Emotion Control
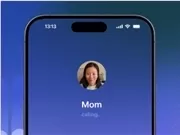
Fish Audio has officially launched its new text-to-speech model, S2, representing a significant leap forward in expressiveness and controllability for open-source TTS technology.
Named Fish Audio S2, this model prioritizes powerful emotional control. Users can make fine-grained adjustments to prosody and emotion using natural language instructions. By inserting tags like [laugh], [whisper], or [super happy], or even using free-form descriptions such as [professional broadcast tone] or [pitch up], it enables precise, word-level control to generate highly expressive and naturally vivid speech.
Key features include:
Completely open source: The model weights, fine-tuning code, and streaming inference engine based on SGLang are all publicly available on GitHub and Hugging Face. S2-Pro is the flagship version with approximately 4.4 billion parameters.Ultra-low latency: Inference latency is under 150 milliseconds, making it ideal for real-time applications like chatbots and virtual streamers.Native multi-speaker support: It can process multiple speakers in a single inference, handling conversational turns, interruptions, and natural emotional delivery while maintaining consistent voice quality without extra processing.Fish Audio reports that S2 was trained on roughly 10 million hours of audio data spanning nearly 50 languages. Utilizing reinforcement learning alignment and a dual autoregressive architecture, it demonstrates leading naturalness and expressiveness in multiple benchmarks. It is considered one of the most emotionally intelligent TTS systems available, open-source or proprietary. "True linguistic freedom starts now," Fish Audio announced, marking the arrival of AI speech with genuine emotion and personality.
GitHub:https://github.com/fishaudio/fish-speech/
HuggingFace:https://huggingface.co/fishaudio/s2-pro/
Related article
 Nvidia H200 China deal survives Trump-Xi summit, but not as expected
President Trump traveled to Beijing with Jensen Huang joining the delegation at the eleventh hour, departing two days later with vague remarks about potential chip export developments. No deal materialized. Since Trump first authorized sales in Decem
How to fix Core Web Vitals for SEO ranking?
Creating visually appealing assets is crucial in game development. Pixel art, with its charming retro aesthetic, remains a popular choice. With the advent of AI tools, generating pixel art has become more accessible than ever. This guide explores how
TechCrunch Disrupt 2026 breakout session agenda unveiled
TechCrunch Disrupt 2026 arrives at Moscone West in San Francisco, October 13–15, uniting 10,000+ founders, investors, operators, and tech leaders for three days of insight, networking, and forward-looking dialogue. Register now to save up to $100 on
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
Fish Audio has officially launched its new text-to-speech model, S2, representing a significant leap forward in expressiveness and controllability for open-source TTS technology.
Named Fish Audio S2, this model prioritizes powerful emotional control. Users can make fine-grained adjustments to prosody and emotion using natural language instructions. By inserting tags like [laugh], [whisper], or [super happy], or even using free-form descriptions such as [professional broadcast tone] or [pitch up], it enables precise, word-level control to generate highly expressive and naturally vivid speech.
Key features include:
Completely open source: The model weights, fine-tuning code, and streaming inference engine based on SGLang are all publicly available on GitHub and Hugging Face. S2-Pro is the flagship version with approximately 4.4 billion parameters.Ultra-low latency: Inference latency is under 150 milliseconds, making it ideal for real-time applications like chatbots and virtual streamers.Native multi-speaker support: It can process multiple speakers in a single inference, handling conversational turns, interruptions, and natural emotional delivery while maintaining consistent voice quality without extra processing.Fish Audio reports that S2 was trained on roughly 10 million hours of audio data spanning nearly 50 languages. Utilizing reinforcement learning alignment and a dual autoregressive architecture, it demonstrates leading naturalness and expressiveness in multiple benchmarks. It is considered one of the most emotionally intelligent TTS systems available, open-source or proprietary. "True linguistic freedom starts now," Fish Audio announced, marking the arrival of AI speech with genuine emotion and personality.
GitHub:https://github.com/fishaudio/fish-speech/
HuggingFace:https://huggingface.co/fishaudio/s2-pro/








 Nvidia H200 China deal survives Trump-Xi summit, but not as expected
President Trump traveled to Beijing with Jensen Huang joining the delegation at the eleventh hour, departing two days later with vague remarks about potential chip export developments. No deal materialized. Since Trump first authorized sales in Decem
 How to fix Core Web Vitals for SEO ranking?
Creating visually appealing assets is crucial in game development. Pixel art, with its charming retro aesthetic, remains a popular choice. With the advent of AI tools, generating pixel art has become more accessible than ever. This guide explores how
 TechCrunch Disrupt 2026 breakout session agenda unveiled
TechCrunch Disrupt 2026 arrives at Moscone West in San Francisco, October 13–15, uniting 10,000+ founders, investors, operators, and tech leaders for three days of insight, networking, and forward-looking dialogue. Register now to save up to $100 on

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












