


 Home
ByteDance Unveils Seed Audio 1.0, Revolutionizing Audio Creation with New Speech-to-Content Tool
Recently, ByteDance introduced Seed Audio 1.0, its new audio creation model, marking a significant advancement in AI audio generation. This update moves the technology beyond basic speech synthesis to enable the creation of fully integrated sound scenes. The model is currently available for creators to test at the Volcano Fangzhou Experience Center.
Traditionally, producing audio content on par with that used in films and television required multiple separate models to generate vocals, sound effects, and ambient noises, which were then manually combined. This approach was time-consuming and made it challenging to maintain consistent storytelling throughout the audio. Seed Audio 1.0 addresses this issue by integrating all audio elements within a single framework rather than simply combining pre-made materials, allowing it to produce complete sound works that support end-to-end storytelling.
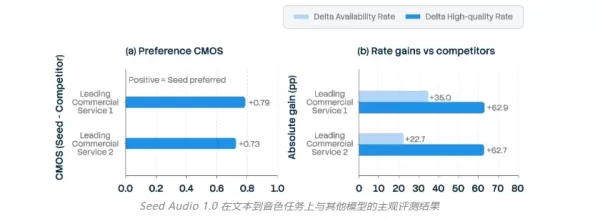
According to the official details, Seed Audio 1.0 features three key capabilities. First, it offers precise temporal-spatial control, enabling creators to set the exact timing for dialogue and sound effects with accuracy down to 100 milliseconds, which is ideal for video dubbing and advertising production. Second, it delivers stable voice performance, supporting zero-shot generation and extended audio output while preserving the character’s voice characteristics. It can also convey a range of emotions such as anger or joy naturally, and even allow one voice to represent multiple characters. Third, it provides robust multilingual support for over 20 languages, including Chinese, English, and Japanese, ensuring the voice sounds natural and fits the local linguistic patterns of each language.
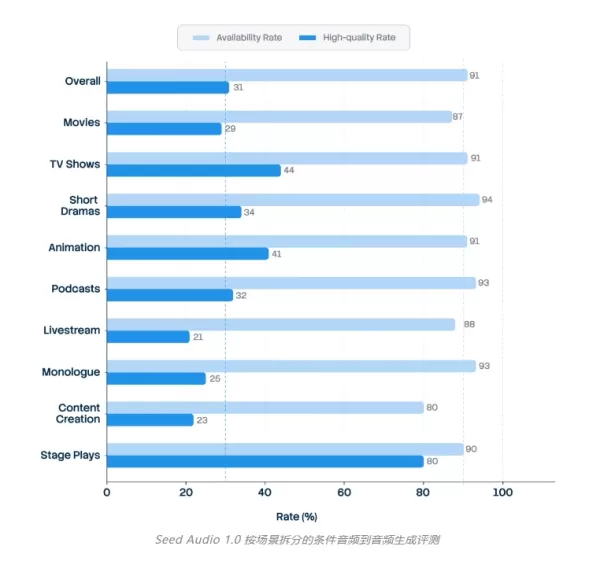
Evaluation results show that the model performs well in nine common creative scenarios, with audio availability exceeding 90%. Additionally, its naturalness MOS score for multilingual generation typically falls above 4 points, which is considered an excellent rating.
By evolving from a tool that can only generate speech to one that can create complete audio content, Seed Audio 1.0 lowers the barriers to producing high-quality audio material. The development team plans to further enhance the model by incorporating multimodal inputs such as video references and exploring controllable translation features. They also aim to continue improving long audio and track generation capabilities, helping creators turn their conceptual sound ideas into fully functional audio works more efficiently.
Project Homepage:
https://seed.bytedance.com/seedaudio1_0
Experience Access:
Volcano Fangzhou Experience Center - Login - Select Voice Model - Voice Synthesis - Doubao - Audio Generation - 1.0
Related article
 Swedish AI Startup Lovable Eyes $13.2 Billion Valuation After Major Funding Round
As AI-driven coding tools gain traction, Swedish startup Lovable has secured a major funding round. The company aims to raise $3 billion, potentially boosting its valuation to $13.2 billion—double the $6.6 billion recorded last December. Menlo Ventur
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int
How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust
Related Special Topic Recommendations
writing
 Best AI Outline Generators for Long-Form SEO Articles
2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
 8 tools
 xix.ai
Education and Learning
AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

 Comments (0)
0/500
Recently, ByteDance introduced Seed Audio 1.0, its new audio creation model, marking a significant advancement in AI audio generation. This update moves the technology beyond basic speech synthesis to enable the creation of fully integrated sound scenes. The model is currently available for creators to test at the Volcano Fangzhou Experience Center.
Traditionally, producing audio content on par with that used in films and television required multiple separate models to generate vocals, sound effects, and ambient noises, which were then manually combined. This approach was time-consuming and made it challenging to maintain consistent storytelling throughout the audio. Seed Audio 1.0 addresses this issue by integrating all audio elements within a single framework rather than simply combining pre-made materials, allowing it to produce complete sound works that support end-to-end storytelling.
According to the official details, Seed Audio 1.0 features three key capabilities. First, it offers precise temporal-spatial control, enabling creators to set the exact timing for dialogue and sound effects with accuracy down to 100 milliseconds, which is ideal for video dubbing and advertising production. Second, it delivers stable voice performance, supporting zero-shot generation and extended audio output while preserving the character’s voice characteristics. It can also convey a range of emotions such as anger or joy naturally, and even allow one voice to represent multiple characters. Third, it provides robust multilingual support for over 20 languages, including Chinese, English, and Japanese, ensuring the voice sounds natural and fits the local linguistic patterns of each language.
Evaluation results show that the model performs well in nine common creative scenarios, with audio availability exceeding 90%. Additionally, its naturalness MOS score for multilingual generation typically falls above 4 points, which is considered an excellent rating.
By evolving from a tool that can only generate speech to one that can create complete audio content, Seed Audio 1.0 lowers the barriers to producing high-quality audio material. The development team plans to further enhance the model by incorporating multimodal inputs such as video references and exploring controllable translation features. They also aim to continue improving long audio and track generation capabilities, helping creators turn their conceptual sound ideas into fully functional audio works more efficiently.
Project Homepage:
https://seed.bytedance.com/seedaudio1_0
Experience Access:
Volcano Fangzhou Experience Center - Login - Select Voice Model - Voice Synthesis - Doubao - Audio Generation - 1.0








 Swedish AI Startup Lovable Eyes $13.2 Billion Valuation After Major Funding Round
As AI-driven coding tools gain traction, Swedish startup Lovable has secured a major funding round. The company aims to raise $3 billion, potentially boosting its valuation to $13.2 billion—double the $6.6 billion recorded last December. Menlo Ventur
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int
 How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust

2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai












