


 Home
AMD's vLLM-ATOM Plugin Boosts Inference for Domestic Large AI Models
AMD has officially launched the vLLM-ATOM plugin, specifically designed for deploying large language models. This plugin aims to significantly enhance the inference performance of mainstream domestic large models like DeepSeek-R1 and Kimi-K2 on AMD hardware, all without disrupting existing workflows.
As an open-source inference framework built for high-concurrency scenarios, vLLM is renowned for its high memory efficiency. The new plugin from AMD delivers a more customized optimization solution for its Instinct series GPUs, enabling developers to achieve technical migration with minimal learning effort.
Seamless Performance Enhancement
The core advantage of the vLLM-ATOM plugin is its "zero-cost" deployment. Users are not required to modify their existing APIs or end-to-end workflows. The plugin automatically manages and optimizes request scheduling and kernel tuning in the background, allowing current services to transition smoothly to the AMD hardware backend.
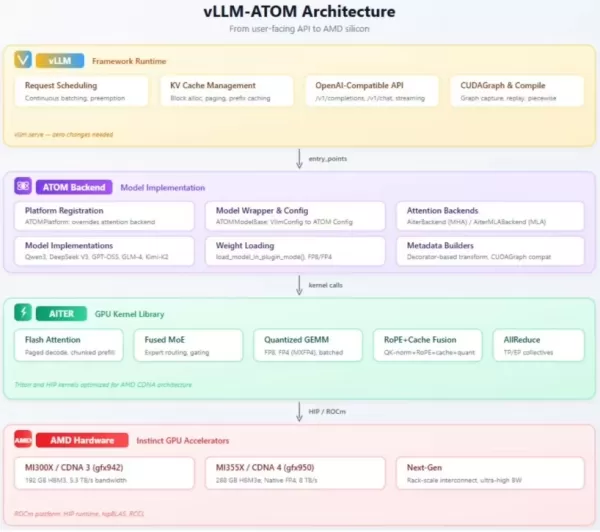
Architecturally, the plugin is structured in three layers: the top layer ensures compatibility with the OpenAI interface, the middle layer handles model execution and routing, and the bottom layer provides the core GPU kernels. This design effectively integrates mixture-of-experts (MoE) and quantization technologies, guaranteeing robust support for large-scale deployments.
Broad Compatibility Across Compute Ecosystems
The plugin targets AMD's Instinct MI350 and MI400 series high-performance GPUs. It supports not only leading Chinese large language models such as Qwen3 and GLM but also comprehensively covers diverse application scenarios, including dense models, mixture-of-experts models, and vision-language models (VLMs).
Related article
 Swedish AI Startup Lovable Eyes $13.2 Billion Valuation After Major Funding Round
As AI-driven coding tools gain traction, Swedish startup Lovable has secured a major funding round. The company aims to raise $3 billion, potentially boosting its valuation to $13.2 billion—double the $6.6 billion recorded last December. Menlo Ventur
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int
How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust
Related Special Topic Recommendations
writing
 Best AI Outline Generators for Long-Form SEO Articles
2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
 8 tools
 xix.ai
Education and Learning
AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

 Comments (0)
0/500
AMD has officially launched the vLLM-ATOM plugin, specifically designed for deploying large language models. This plugin aims to significantly enhance the inference performance of mainstream domestic large models like DeepSeek-R1 and Kimi-K2 on AMD hardware, all without disrupting existing workflows.
As an open-source inference framework built for high-concurrency scenarios, vLLM is renowned for its high memory efficiency. The new plugin from AMD delivers a more customized optimization solution for its Instinct series GPUs, enabling developers to achieve technical migration with minimal learning effort.
Seamless Performance Enhancement
The core advantage of the vLLM-ATOM plugin is its "zero-cost" deployment. Users are not required to modify their existing APIs or end-to-end workflows. The plugin automatically manages and optimizes request scheduling and kernel tuning in the background, allowing current services to transition smoothly to the AMD hardware backend.
Architecturally, the plugin is structured in three layers: the top layer ensures compatibility with the OpenAI interface, the middle layer handles model execution and routing, and the bottom layer provides the core GPU kernels. This design effectively integrates mixture-of-experts (MoE) and quantization technologies, guaranteeing robust support for large-scale deployments.
Broad Compatibility Across Compute Ecosystems
The plugin targets AMD's Instinct MI350 and MI400 series high-performance GPUs. It supports not only leading Chinese large language models such as Qwen3 and GLM but also comprehensively covers diverse application scenarios, including dense models, mixture-of-experts models, and vision-language models (VLMs).








 Swedish AI Startup Lovable Eyes $13.2 Billion Valuation After Major Funding Round
As AI-driven coding tools gain traction, Swedish startup Lovable has secured a major funding round. The company aims to raise $3 billion, potentially boosting its valuation to $13.2 billion—double the $6.6 billion recorded last December. Menlo Ventur
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int
 How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust

2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai












