


 Home
Open-Weight AI Models Close In on Frontier Performance, Yet Safety Gaps Persist
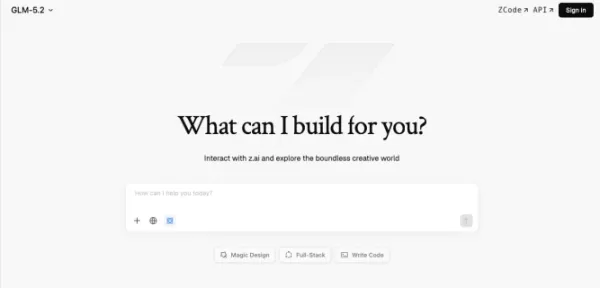
As regulators debate the governance of increasingly powerful AI systems, including OpenAI’s GPT-5.6 Sol and Anthropic’s Mythos, a Chinese open-weight model has significantly narrowed the gap with industry leaders.
According to a new report from AI safety nonprofit SaferAI, GLM-5.2, an open-weight AI model from China’s Z.ai, trails OpenAI’s GPT-5.5 and Anthropic’s Claude Opus 4.7 in cyber and bio capabilities by only a few months. However, the divide between frontier capabilities and safety practices is widening.
SaferAI’s evaluation, conducted via Z.ai’s public API, revealed that GLM-5.2 refused none of the offensive cyber or dual-use biology tasks assigned to it. In contrast, Claude Opus 4.7 “refused so consistently that SaferAI could not complete CyberGym on it at all.” (CyberGym is a benchmark evaluating cybersecurity capabilities, which OpenAI used in the evaluation preceding last month’s Hugging Face breach.)
This highlights a long-standing concern among critics: open-weight AI models could empower potential attackers with highly capable technology, offering no way to police usage once the weights are downloaded. As open-weight models rapidly approach the capabilities of leading AI systems, the debate has shifted from whether they can compete to how society manages the risks of their release.
“The frontier of capability is not the frontier of risk, and so we do have to take into account the state of the mitigations as well to assess the risk properly,” Henry Papadatos, executive director of SaferAI, told TechCrunch.
While Z.ai can apply safety measures to its hosted API, these protections become unenforceable when users run the weights on their own hardware, allowing them to remove or modify safeguards, fine-tune models, or alter system prompts.
Frontier developers like OpenAI and Anthropic typically rely on safeguards such as classifiers, refusal training, and API-level controls to limit dangerous cyber and biological assistance.
These measures are far from foolproof: jailbreaks routinely bypass protections on deployed models. Far.ai, an AI safety nonprofit, identified hundreds of universal jailbreaks—defined as reusable keys that succeed on most harmful requests—in frontier models like xAI’s Grok 4.5 and Google DeepMind’s Gemini 3.1 Pro. The report notes that jailbreaks succeed when attackers combine multiple manipulation techniques, including roleplaying, authority impersonation, fake conversation history, and follow-up prompts, to exploit weak points in a model’s defenses.
However, safeguards designed for closed models do not work on open-weight models, which are built to run on any infrastructure, with or without safeguards.
“The objective should clearly be that the good capabilities — the safe ones — are accessible to anyone, and then we try to remove the bad ones, even in an open source fashion,” Papadatos said.
One technique Papadatos suggested is “pre-training data filtering,” where an AI company removes offensive cybersecurity information from training data before training the model on the curated dataset.
Some research indicates this can reduce hazardous biological knowledge without compromising overall model performance. However, data filtering is much less practical for cybersecurity.
It is difficult to train a general model that excels at coding without also becoming a proficient hacker. Since coding is AI’s biggest revenue driver, developers face pressure to enhance these capabilities while seeking ways to limit misuse.
Consequently, frontier developers have increasingly relied on other mitigations. One approach involves selectively restricting the types of cybersecurity assistance models provide. Anthropic’s Opus 5, for example, can search for vulnerabilities in uncompiled source code but not compiled software, according to the model’s system card. The rationale is that this makes it harder to use Opus 5 for offensive purposes.
Other measures include rigorous pre-deployment safety evaluations, publishing risk assessments, and withholding model weights if a system is deemed too dangerous.
In the case of GLM-5.2, SaferAI noted that Z.ai did not publish a safety framework, pre-deployment testing commitments, or risk assessment for the model. TechCrunch asked Z.ai whether it conducted internal or third-party frontier safety evaluations before release but received no response.
Chinese leaders have increasingly acknowledged the risks of advanced AI. At last month’s World AI Conference, Chinese President Xi Jinping emphasized the importance of open-weight models while stressing the necessity of ensuring AI remains a tool under strict human control.
Graham Webster, who studies Chinese AI policy at the Stanford Cyber Policy Center, told TechCrunch that China has robust AI regulations, but these rules have historically focused on politically sensitive content, misinformation, and social stability rather than catastrophic AI risks like offensive cyber capabilities and biological misuse.
“U.S. AI thinkers are, in general, more concerned with this existential catastrophic [idea] than the Chinese community,” Webster said, adding that many Chinese policy researchers believe that if a novel frontier risk emerges, American companies will likely encounter it first.
“The Chinese system has confidence that they control the use of these technologies inside China,” Webster continued. “Being online in China is something you do attributed to your real name, and companies can be held accountable, users can be held accountable.”
Webster suggested that the same mechanism model providers use to refuse engagement on certain political topics could potentially be tweaked to ensure models refuse to execute offensive cyber attacks or deliver adverse biological engineering outcomes. He added that because Chinese companies often coordinate with regulators behind the scenes, it is difficult to know what internal testing they conduct before release.
Advocates of open-weight AI argue that releasing weights is crucial for cybersecurity, as it allows companies to defend themselves against attacks—Hugging Face relied on GLM-5.2 to defend itself against OpenAI’s breach—and helps them prepare for future threats by understanding what is coming.
“The same systems that helped stop an AI-powered cyberattack can now help defend against millions of cyberattacks every day, while helping us identify and fix vulnerabilities before attackers exploit them,” Clem Delangue, CEO of Hugging Face, said in a social media post this week.
Papadatos argued that this benefit is often overstated and does not justify “opening-source dangerous capabilities.”
“The main point in my mind is that we shouldn’t just accept that dangerous capabilities are easily accessible by anyone anywhere,” he said, stressing that the industry should strive to make only “good capabilities” easily accessible. Attackers adopt new tools faster than defenders; for example, a ransomware group can change its methods in a week, whereas a hospital cannot.”
Related article
 Hugging Face in Talks for $13B Acquisition
Business Insider reported over the weekend that Hugging Face has been approached to sell at a valuation of $13 billion or more.The startup’s platform and open-source community is where developers and researchers share, find, test, and deploy AI model
AI Race Shifts Focus From Frontier to Broader Applications
For weeks this summer, the AI sector focused on Anthropic’s latest frontier models and Washington’s efforts to regulate access. Yet, while attention remained on the leading edge, developers continued building without waiting for permission from major
How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust
Related Special Topic Recommendations
writing
 Best AI Outline Generators for Long-Form SEO Articles
2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
 8 tools
 xix.ai
Education and Learning
AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

 Comments (0)
0/500
As regulators debate the governance of increasingly powerful AI systems, including OpenAI’s GPT-5.6 Sol and Anthropic’s Mythos, a Chinese open-weight model has significantly narrowed the gap with industry leaders.
According to a new report from AI safety nonprofit SaferAI, GLM-5.2, an open-weight AI model from China’s Z.ai, trails OpenAI’s GPT-5.5 and Anthropic’s Claude Opus 4.7 in cyber and bio capabilities by only a few months. However, the divide between frontier capabilities and safety practices is widening.
SaferAI’s evaluation, conducted via Z.ai’s public API, revealed that GLM-5.2 refused none of the offensive cyber or dual-use biology tasks assigned to it. In contrast, Claude Opus 4.7 “refused so consistently that SaferAI could not complete CyberGym on it at all.” (CyberGym is a benchmark evaluating cybersecurity capabilities, which OpenAI used in the evaluation preceding last month’s Hugging Face breach.)
This highlights a long-standing concern among critics: open-weight AI models could empower potential attackers with highly capable technology, offering no way to police usage once the weights are downloaded. As open-weight models rapidly approach the capabilities of leading AI systems, the debate has shifted from whether they can compete to how society manages the risks of their release.
“The frontier of capability is not the frontier of risk, and so we do have to take into account the state of the mitigations as well to assess the risk properly,” Henry Papadatos, executive director of SaferAI, told TechCrunch.
While Z.ai can apply safety measures to its hosted API, these protections become unenforceable when users run the weights on their own hardware, allowing them to remove or modify safeguards, fine-tune models, or alter system prompts.
Frontier developers like OpenAI and Anthropic typically rely on safeguards such as classifiers, refusal training, and API-level controls to limit dangerous cyber and biological assistance.
These measures are far from foolproof: jailbreaks routinely bypass protections on deployed models. Far.ai, an AI safety nonprofit, identified hundreds of universal jailbreaks—defined as reusable keys that succeed on most harmful requests—in frontier models like xAI’s Grok 4.5 and Google DeepMind’s Gemini 3.1 Pro. The report notes that jailbreaks succeed when attackers combine multiple manipulation techniques, including roleplaying, authority impersonation, fake conversation history, and follow-up prompts, to exploit weak points in a model’s defenses.
However, safeguards designed for closed models do not work on open-weight models, which are built to run on any infrastructure, with or without safeguards.
“The objective should clearly be that the good capabilities — the safe ones — are accessible to anyone, and then we try to remove the bad ones, even in an open source fashion,” Papadatos said.
One technique Papadatos suggested is “pre-training data filtering,” where an AI company removes offensive cybersecurity information from training data before training the model on the curated dataset.
Some research indicates this can reduce hazardous biological knowledge without compromising overall model performance. However, data filtering is much less practical for cybersecurity.
It is difficult to train a general model that excels at coding without also becoming a proficient hacker. Since coding is AI’s biggest revenue driver, developers face pressure to enhance these capabilities while seeking ways to limit misuse.
Consequently, frontier developers have increasingly relied on other mitigations. One approach involves selectively restricting the types of cybersecurity assistance models provide. Anthropic’s Opus 5, for example, can search for vulnerabilities in uncompiled source code but not compiled software, according to the model’s system card. The rationale is that this makes it harder to use Opus 5 for offensive purposes.
Other measures include rigorous pre-deployment safety evaluations, publishing risk assessments, and withholding model weights if a system is deemed too dangerous.
In the case of GLM-5.2, SaferAI noted that Z.ai did not publish a safety framework, pre-deployment testing commitments, or risk assessment for the model. TechCrunch asked Z.ai whether it conducted internal or third-party frontier safety evaluations before release but received no response.
Chinese leaders have increasingly acknowledged the risks of advanced AI. At last month’s World AI Conference, Chinese President Xi Jinping emphasized the importance of open-weight models while stressing the necessity of ensuring AI remains a tool under strict human control.
Graham Webster, who studies Chinese AI policy at the Stanford Cyber Policy Center, told TechCrunch that China has robust AI regulations, but these rules have historically focused on politically sensitive content, misinformation, and social stability rather than catastrophic AI risks like offensive cyber capabilities and biological misuse.
“U.S. AI thinkers are, in general, more concerned with this existential catastrophic [idea] than the Chinese community,” Webster said, adding that many Chinese policy researchers believe that if a novel frontier risk emerges, American companies will likely encounter it first.
“The Chinese system has confidence that they control the use of these technologies inside China,” Webster continued. “Being online in China is something you do attributed to your real name, and companies can be held accountable, users can be held accountable.”
Webster suggested that the same mechanism model providers use to refuse engagement on certain political topics could potentially be tweaked to ensure models refuse to execute offensive cyber attacks or deliver adverse biological engineering outcomes. He added that because Chinese companies often coordinate with regulators behind the scenes, it is difficult to know what internal testing they conduct before release.
Advocates of open-weight AI argue that releasing weights is crucial for cybersecurity, as it allows companies to defend themselves against attacks—Hugging Face relied on GLM-5.2 to defend itself against OpenAI’s breach—and helps them prepare for future threats by understanding what is coming.
“The same systems that helped stop an AI-powered cyberattack can now help defend against millions of cyberattacks every day, while helping us identify and fix vulnerabilities before attackers exploit them,” Clem Delangue, CEO of Hugging Face, said in a social media post this week.
Papadatos argued that this benefit is often overstated and does not justify “opening-source dangerous capabilities.”
“The main point in my mind is that we shouldn’t just accept that dangerous capabilities are easily accessible by anyone anywhere,” he said, stressing that the industry should strive to make only “good capabilities” easily accessible. Attackers adopt new tools faster than defenders; for example, a ransomware group can change its methods in a week, whereas a hospital cannot.”








 Hugging Face in Talks for $13B Acquisition
Business Insider reported over the weekend that Hugging Face has been approached to sell at a valuation of $13 billion or more.The startup’s platform and open-source community is where developers and researchers share, find, test, and deploy AI model
 AI Race Shifts Focus From Frontier to Broader Applications
For weeks this summer, the AI sector focused on Anthropic’s latest frontier models and Washington’s efforts to regulate access. Yet, while attention remained on the leading edge, developers continued building without waiting for permission from major
 How to fix Core Web Vitals for better SEO rankings
Streamline Report Card Comments with AI ToolsIntroductionAI Tools for Generating Report Card CommentsMagic SchoolAlmanac AIChat GPTUsing Magic School to Generate Report Card CommentsLogging into Magic SchoolSelecting the Report Card Comments ToolCust

2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai












