


 Home
AI 'Reasoning' Models Surge, Driving Up Benchmarking Costs
The Rising Costs of Benchmarking AI Reasoning Models
AI labs like OpenAI have been touting their advanced "reasoning" AI models, which are designed to tackle complex problems step by step. These models, particularly effective in fields like physics, are indeed impressive. However, they come with a hefty price tag when it comes to benchmarking, making it challenging for independent verification of their capabilities.
According to data from Artificial Analysis, a third-party AI testing firm, the cost to evaluate OpenAI's o1 reasoning model across seven popular AI benchmarks is a staggering $2,767.05. These benchmarks include MMLU-Pro, GPQA Diamond, Humanity’s Last Exam, LiveCodeBench, SciCode, AIME 2024, and MATH-500. In contrast, benchmarking Anthropic's "hybrid" reasoning model, Claude 3.7 Sonnet, on the same tests cost $1,485.35, while OpenAI's o3-mini-high was significantly cheaper at $344.59.
Not all reasoning models are equally expensive to test. For instance, Artificial Analysis spent only $141.22 evaluating OpenAI’s o1-mini. However, the costs of these models tend to be high on average. Artificial Analysis has shelled out around $5,200 to evaluate about a dozen reasoning models, which is nearly double the $2,400 spent on analyzing over 80 non-reasoning models.
For comparison, the non-reasoning GPT-4o model from OpenAI, released in May 2024, cost Artificial Analysis just $108.85 to evaluate, while Claude 3.6 Sonnet, the non-reasoning predecessor to Claude 3.7 Sonnet, cost $81.41.
George Cameron, co-founder of Artificial Analysis, shared with TechCrunch that the organization is prepared to increase its benchmarking budget as more AI labs continue to develop reasoning models. "At Artificial Analysis, we run hundreds of evaluations monthly and devote a significant budget to these," Cameron stated. "We are planning for this spend to increase as models are more frequently released."
Artificial Analysis isn't alone in facing these escalating costs. Ross Taylor, CEO of AI startup General Reasoning, recently spent $580 to evaluate Claude 3.7 Sonnet on around 3,700 unique prompts. Taylor estimates that a single run-through of MMLU Pro, a benchmark designed to test language comprehension, would exceed $1,800.
Taylor highlighted a growing concern in a recent post on X, stating, "We’re moving to a world where a lab reports x% on a benchmark where they spend y amount of compute, but where resources for academics are << y. No one is going to be able to reproduce the results."
Why Are Reasoning Models So Expensive to Benchmark?
The primary reason for the high cost of testing reasoning models is their tendency to generate a substantial number of tokens. Tokens are units of raw text; for example, the word "fantastic" might be broken down into "fan," "tas," and "tic." According to Artificial Analysis, OpenAI's o1 model generated over 44 million tokens during their tests, which is roughly eight times the number of tokens generated by the non-reasoning GPT-4o model.
Most AI companies charge for model usage based on the number of tokens, which quickly adds up. Additionally, modern benchmarks are designed to elicit a high number of tokens by including questions that involve complex, multi-step tasks. Jean-Stanislas Denain, a senior researcher at Epoch AI, explained to TechCrunch, "Today’s benchmarks are more complex even though the number of questions per benchmark has overall decreased. They often attempt to evaluate models’ ability to do real-world tasks, such as write and execute code, browse the internet, and use computers."
Denain also pointed out that the cost per token for the most expensive models has been rising. For example, when Anthropic's Claude 3 Opus was released in May 2024, it cost $75 per million output tokens. In contrast, OpenAI's GPT-4.5 and o1-pro, launched earlier that year, cost $150 and $600 per million output tokens, respectively.
Despite the increasing cost per token, Denain noted, "Since models have gotten better over time, it’s still true that the cost to reach a given level of performance has greatly decreased over time. But if you want to evaluate the best largest models at any point in time, you’re still paying more."
The Integrity of Benchmarking
Many AI labs, including OpenAI, offer free or subsidized access to their models for benchmarking purposes. However, this practice raises concerns about the integrity of the evaluation process. Even without evidence of manipulation, the mere suggestion of an AI lab's involvement can cast doubt on the objectivity of the results.
Ross Taylor expressed this concern on X, asking, "From a scientific point of view, if you publish a result that no one can replicate with the same model, is it even science anymore? (Was it ever science, lol)"
The high costs and potential biases in AI benchmarking underscore the challenges facing the field as it strives to develop and validate increasingly sophisticated models.
Related article
 Apple, Google Partner With Anthropic to Address 27-Year-Old Vulnerability via Glass Wing Protection
As artificial intelligence advances rapidly in code generation and logical reasoning, the cybersecurity landscape faces unprecedented challenges. Recently, the prominent AI startup Anthropic officially launched a cross-industry collaboration called *
OpenAI Chief Scientist Addresses AI Reasoning Transparency Debate: Complexity Steady, No Sudden Jump
On September 2, Jakub Pachocki, OpenAI’s Chief Scientist, addressed public concerns on X regarding the AI model Astra, clarifying claims that it operates without oversight and lacks transparent reasoning.Why the Controversy Erupted: Deep Recurrence O
U.S. Navy Selects Blue Water Autonomy for Deep-Sea Survey Missions
Blue Water Autonomy’s Liberty Class is a 190-foot steel autonomous ship. | Source: Blue Water AutonomyBoston-based technology and shipbuilding firm Blue Water Autonomy has secured a multiple-award contract with the Naval Oceanographic Office (NAVOCEA
Related Special Topic Recommendations
Text-to-speech
 Best AI Text to Speech Tools for Online Courses
2026 Latest Best Top-rated AI Text to Speech Tools for Online Courses are curated by XIX.AI based on rigorous real-world tests and weekly updated rankings. These powerful tools help creators deliver crystal-clear audio content effortlessly, boosting writing efficiency and streamlining course production. Check out the free vs paid comparison to find your perfect fit. Explore now to unlock your AI edge in online education.
 10 tools
 xix.ai
writing
AI Blog Title Tools for Higher Click Through Rates
2026 Latest Best Top-Rated AI Blog Title Tools for Higher Click Through Rates! XIX.AI has carefully curated a powerful, game-changing collection of top tools that go through rigorous real-world tests. You’ll find a free vs paid comparison, weekly updated rankings, and detailed insights to help you boost your blog’s traffic efficiently. Must-try options are highlighted to help you unlock your AI edge. Explore now!
10 tools
xix.ai
automation
Best AI Task Routing Tools for Support Workflows
2026 Latest Best Top-rated AI Task Routing Tools for Support Workflows! XIX.AI has curated a highly powerful game-changing collection of must-try solutions, all undergoing rigorous real-world tests and updated weekly. These tools streamline workflows, boost productivity, and help teams deliver faster, more efficient support. Explore now to discover your perfect tool and unlock your AI edge!
17 tools
xix.ai
Academic Research
AI Citation and Paper Summary Tools
2026 Latest Best Top-Rated AI Citation and Paper Summary Tools Curated by XIX.AI. Get powerful game-changing solutions for quick content creation, improved writing efficiency, and boosting productivity. We offer a free vs paid comparison along with real-world tests and weekly updated rankings to help you find the must-try tool that fits your needs perfectly. Explore now to Unlock your AI edge.
10 tools
xix.ai
Productivity
Best AI Productivity Tools for Daily Work
2026 Latest Best Top-Rated AI Productivity Tools for Daily Work! XIX.AI has curated a powerful, game-changing selection based on rigorous weekly updated rankings and real-world tests. You’ll find must-try options that boost writing efficiency, streamline content creation, and help you overcome daily work challenges. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge!
9 tools
xix.ai
Academic Research
AI Systematic Review Tools for Research Screening
2026 Latest Best Top-Rated AI Systematic Review Tools for Research Screening are here on XIX.AI! This curated collection includes powerful, game-changing solutions that go through rigorous real-world tests to deliver accurate results. We also offer a free vs paid comparison along with weekly updated rankings to help you find the must-try option that boosts your research efficiency significantly. Explore now to unlock your AI edge in academic work!
11 tools
xix.ai

 Comments (18)
0/500
![PatrickCarter]()
推理模型确实强大,但算钱如流水,普通开发者怎么跟大厂卷?😂
![FrankJackson]()
These AI reasoning models are impressive for tackling complex physics problems step by step, but the surging benchmarking costs could stifle innovation for smaller labs. 😟 Reminds me of how tech giants dominate—maybe we need more affordable alternatives?
![DouglasRodriguez]()
These AI reasoning models sound cool, but the skyrocketing benchmarking costs are wild! 😳 Makes me wonder if smaller labs can even keep up with the big players like OpenAI.
![StevenGonzalez]()
These AI reasoning models are impressive, but the rising costs of benchmarking are a real bummer. It's great for fields like physics, but I hope they find a way to make it more affordable. Otherwise, it's just for the big players. 😕
![JackPerez]()
Esses modelos de raciocínio de IA são impressionantes, mas o aumento dos custos de benchmarking é uma decepção. É ótimo para áreas como a física, mas espero que encontrem uma maneira de torná-lo mais acessível. Caso contrário, será apenas para os grandes jogadores. 😕
![GregoryJones]()
AI推論モデルは素晴らしいけど、ベンチマーキングのコストが上がるのは残念です。物理分野には良いけど、もっと手頃な価格になる方法を見つけてほしいです。さもないと、大手企業だけのものになってしまいますね。😕
The Rising Costs of Benchmarking AI Reasoning Models
AI labs like OpenAI have been touting their advanced "reasoning" AI models, which are designed to tackle complex problems step by step. These models, particularly effective in fields like physics, are indeed impressive. However, they come with a hefty price tag when it comes to benchmarking, making it challenging for independent verification of their capabilities.
According to data from Artificial Analysis, a third-party AI testing firm, the cost to evaluate OpenAI's o1 reasoning model across seven popular AI benchmarks is a staggering $2,767.05. These benchmarks include MMLU-Pro, GPQA Diamond, Humanity’s Last Exam, LiveCodeBench, SciCode, AIME 2024, and MATH-500. In contrast, benchmarking Anthropic's "hybrid" reasoning model, Claude 3.7 Sonnet, on the same tests cost $1,485.35, while OpenAI's o3-mini-high was significantly cheaper at $344.59.
Not all reasoning models are equally expensive to test. For instance, Artificial Analysis spent only $141.22 evaluating OpenAI’s o1-mini. However, the costs of these models tend to be high on average. Artificial Analysis has shelled out around $5,200 to evaluate about a dozen reasoning models, which is nearly double the $2,400 spent on analyzing over 80 non-reasoning models.
For comparison, the non-reasoning GPT-4o model from OpenAI, released in May 2024, cost Artificial Analysis just $108.85 to evaluate, while Claude 3.6 Sonnet, the non-reasoning predecessor to Claude 3.7 Sonnet, cost $81.41.
George Cameron, co-founder of Artificial Analysis, shared with TechCrunch that the organization is prepared to increase its benchmarking budget as more AI labs continue to develop reasoning models. "At Artificial Analysis, we run hundreds of evaluations monthly and devote a significant budget to these," Cameron stated. "We are planning for this spend to increase as models are more frequently released."
Artificial Analysis isn't alone in facing these escalating costs. Ross Taylor, CEO of AI startup General Reasoning, recently spent $580 to evaluate Claude 3.7 Sonnet on around 3,700 unique prompts. Taylor estimates that a single run-through of MMLU Pro, a benchmark designed to test language comprehension, would exceed $1,800.
Taylor highlighted a growing concern in a recent post on X, stating, "We’re moving to a world where a lab reports x% on a benchmark where they spend y amount of compute, but where resources for academics are << y. No one is going to be able to reproduce the results."
Why Are Reasoning Models So Expensive to Benchmark?
The primary reason for the high cost of testing reasoning models is their tendency to generate a substantial number of tokens. Tokens are units of raw text; for example, the word "fantastic" might be broken down into "fan," "tas," and "tic." According to Artificial Analysis, OpenAI's o1 model generated over 44 million tokens during their tests, which is roughly eight times the number of tokens generated by the non-reasoning GPT-4o model.
Most AI companies charge for model usage based on the number of tokens, which quickly adds up. Additionally, modern benchmarks are designed to elicit a high number of tokens by including questions that involve complex, multi-step tasks. Jean-Stanislas Denain, a senior researcher at Epoch AI, explained to TechCrunch, "Today’s benchmarks are more complex even though the number of questions per benchmark has overall decreased. They often attempt to evaluate models’ ability to do real-world tasks, such as write and execute code, browse the internet, and use computers."
Denain also pointed out that the cost per token for the most expensive models has been rising. For example, when Anthropic's Claude 3 Opus was released in May 2024, it cost $75 per million output tokens. In contrast, OpenAI's GPT-4.5 and o1-pro, launched earlier that year, cost $150 and $600 per million output tokens, respectively.
Despite the increasing cost per token, Denain noted, "Since models have gotten better over time, it’s still true that the cost to reach a given level of performance has greatly decreased over time. But if you want to evaluate the best largest models at any point in time, you’re still paying more."
The Integrity of Benchmarking
Many AI labs, including OpenAI, offer free or subsidized access to their models for benchmarking purposes. However, this practice raises concerns about the integrity of the evaluation process. Even without evidence of manipulation, the mere suggestion of an AI lab's involvement can cast doubt on the objectivity of the results.
Ross Taylor expressed this concern on X, asking, "From a scientific point of view, if you publish a result that no one can replicate with the same model, is it even science anymore? (Was it ever science, lol)"
The high costs and potential biases in AI benchmarking underscore the challenges facing the field as it strives to develop and validate increasingly sophisticated models.








 Apple, Google Partner With Anthropic to Address 27-Year-Old Vulnerability via Glass Wing Protection
As artificial intelligence advances rapidly in code generation and logical reasoning, the cybersecurity landscape faces unprecedented challenges. Recently, the prominent AI startup Anthropic officially launched a cross-industry collaboration called *
 OpenAI Chief Scientist Addresses AI Reasoning Transparency Debate: Complexity Steady, No Sudden Jump
On September 2, Jakub Pachocki, OpenAI’s Chief Scientist, addressed public concerns on X regarding the AI model Astra, clarifying claims that it operates without oversight and lacks transparent reasoning.Why the Controversy Erupted: Deep Recurrence O
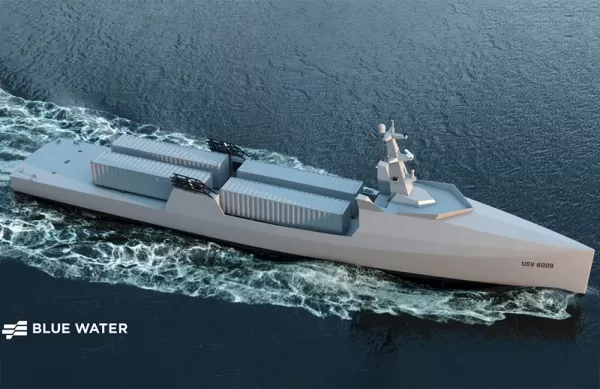 U.S. Navy Selects Blue Water Autonomy for Deep-Sea Survey Missions
Blue Water Autonomy’s Liberty Class is a 190-foot steel autonomous ship. | Source: Blue Water AutonomyBoston-based technology and shipbuilding firm Blue Water Autonomy has secured a multiple-award contract with the Naval Oceanographic Office (NAVOCEA

2026 Latest Best Top-rated AI Text to Speech Tools for Online Courses are curated by XIX.AI based on rigorous real-world tests and weekly updated rankings. These powerful tools help creators deliver crystal-clear audio content effortlessly, boosting writing efficiency and streamlining course production. Check out the free vs paid comparison to find your perfect fit. Explore now to unlock your AI edge in online education.
10 tools
xix.ai

2026 Latest Best Top-Rated AI Blog Title Tools for Higher Click Through Rates! XIX.AI has carefully curated a powerful, game-changing collection of top tools that go through rigorous real-world tests. You’ll find a free vs paid comparison, weekly updated rankings, and detailed insights to help you boost your blog’s traffic efficiently. Must-try options are highlighted to help you unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-rated AI Task Routing Tools for Support Workflows! XIX.AI has curated a highly powerful game-changing collection of must-try solutions, all undergoing rigorous real-world tests and updated weekly. These tools streamline workflows, boost productivity, and help teams deliver faster, more efficient support. Explore now to discover your perfect tool and unlock your AI edge!
17 tools
xix.ai

2026 Latest Best Top-Rated AI Citation and Paper Summary Tools Curated by XIX.AI. Get powerful game-changing solutions for quick content creation, improved writing efficiency, and boosting productivity. We offer a free vs paid comparison along with real-world tests and weekly updated rankings to help you find the must-try tool that fits your needs perfectly. Explore now to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI Productivity Tools for Daily Work! XIX.AI has curated a powerful, game-changing selection based on rigorous weekly updated rankings and real-world tests. You’ll find must-try options that boost writing efficiency, streamline content creation, and help you overcome daily work challenges. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge!
9 tools
xix.ai
2026 Latest Best Top-Rated AI Systematic Review Tools for Research Screening are here on XIX.AI! This curated collection includes powerful, game-changing solutions that go through rigorous real-world tests to deliver accurate results. We also offer a free vs paid comparison along with weekly updated rankings to help you find the must-try option that boosts your research efficiency significantly. Explore now to unlock your AI edge in academic work!
11 tools
xix.ai

推理模型确实强大,但算钱如流水,普通开发者怎么跟大厂卷?😂
These AI reasoning models are impressive for tackling complex physics problems step by step, but the surging benchmarking costs could stifle innovation for smaller labs. 😟 Reminds me of how tech giants dominate—maybe we need more affordable alternatives?
These AI reasoning models sound cool, but the skyrocketing benchmarking costs are wild! 😳 Makes me wonder if smaller labs can even keep up with the big players like OpenAI.
These AI reasoning models are impressive, but the rising costs of benchmarking are a real bummer. It's great for fields like physics, but I hope they find a way to make it more affordable. Otherwise, it's just for the big players. 😕
Esses modelos de raciocínio de IA são impressionantes, mas o aumento dos custos de benchmarking é uma decepção. É ótimo para áreas como a física, mas espero que encontrem uma maneira de torná-lo mais acessível. Caso contrário, será apenas para os grandes jogadores. 😕
AI推論モデルは素晴らしいけど、ベンチマーキングのコストが上がるのは残念です。物理分野には良いけど、もっと手頃な価格になる方法を見つけてほしいです。さもないと、大手企業だけのものになってしまいますね。😕












