


 Home
Microsoft Bing Team Open Sources 27B Embedding Model Harrier, Leading Multilingual Benchmarks
On April 7, Microsoft's Bing team announced the open-source release of a new word embedding model series called "Harrier," designed to reshape the underlying logic of global search, retrieval, and AI agents. The Harrier series includes three versions, with the flagship 27B model surpassing major proprietary models from OpenAI, Amazon, and Google Gemini in the multilingual MTEB v2 benchmark, securing the top spot.
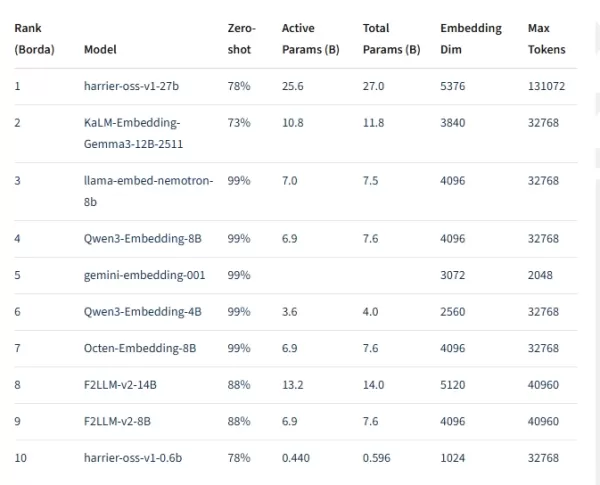
The technical foundation of this model reflects strong industrial standards: Harrier supports over 100 languages with a context window of up to 32,000 tokens. For training, Microsoft used over 2 billion real-world examples and incorporated synthetic data from GPT-5 for reinforcement learning. This high-quality data mix gives Harrier a distinct advantage in understanding complex contexts and handling long texts. Alongside the full 27B-parameter version, Microsoft also released smaller 0.6B and 2.7B variants to accommodate different computing environments, all open-sourced on Hugging Face under the MIT license.
Embedding models are essential for organizing and retrieving information in AI systems, and their performance directly impacts the accuracy of RAG (Retrieval-Augmented Generation) systems. Microsoft intends to integrate this technology into the Bing search engine and new AI agent grounding services. As AI moves toward more autonomous, multi-step tasks, the open-sourcing of Harrier not only gives developers a high-performance alternative to proprietary models but also marks a significant milestone for the open-source ecosystem in semantic representation, further accelerating AI agent deployment in multilingual global environments.
Related article
 ByteDance’s Seed launches global campus drive, offering virtual shares to win top large model talent
In the competitive landscape of large language models, securing top-tier talent remains the most critical strategic asset.On April 1st, ByteDance announced the launch of its Seed global campus recruitment initiative, part of its large model talent de
Suno to Watermark Songs Amid Legal Battles
Suno, the platform enabling users to generate AI-created music, has unveiled new features to label platform-produced tracks, restrict downloads, and update community standards to curb unauthorized replicas. These updates arrive as Suno confronts mult
Musk Admits Grok Build Leaked User Code, Promises to Erase All Historical Data
Elon Musk directly addressed the privacy controversy surrounding Grok Build, beginning with a simple "True" to confirm the incident's validity. He pledged that all user data previously uploaded to SpaceXAI would be permanently erased, stating, "not a
Related Special Topic Recommendations
Design & Art
 AI Visual Style Reference Tools for Character Sheets, Moodboards, and Pitch Decks
2026 Latest Best AI Visual Style Reference Tools for Character Sheets, Moodboards, and Pitch Decks are here on XIX.AI! This curated top-rated list features powerful game-changing tools that go through rigorous real-world tests. You’ll find a free vs paid comparison, detailed rankings, and must-try options to help you boost creativity and streamline your workflow. Explore now to discover your perfect tool for boosting productivity!
 11 tools
 xix.ai
SEO
Best AI SERP Analysis Tools for Search Strategy
2026 Latest Best Top-rated AI SERP Analysis Tools for Search Strategy are curated by XIX.AI through rigorous real-world tests and weekly updated rankings. These powerful tools help you unlock hidden optimization opportunities, boost content performance, and gain a competitive edge in search. Discover your perfect tool to elevate your search strategy today. Explore now!
13 tools
xix.ai
Data Analysis
Best AI Anomaly Detection Tools for KPI Monitoring across SaaS and Ecommerce Teams
2026 Latest Best Top-rated AI Anomaly Detection Tools for KPI Monitoring in SaaS and Ecommerce teams! XIX.AI has curated a powerful, game-changing collection based on rigorous real-world tests and weekly updated rankings. You’ll find detailed free vs paid comparison insights to help you identify the must-try solution that boosts productivity and unlocks your AI edge. Explore now!
10 tools
xix.ai
writing
Best AI Outline Generators for Long-Form SEO Articles
2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai
Education and Learning
AI Study Tools for Homework and Exam Prep
2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai
Music composition
AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

 Comments (1)
0/500
![MatthewHill]()
Finally, an open-source embedding model that actually challenges the big players! Harrier's 27B parameters look promising for multilingual tasks, especially if it improves retrieval accuracy without the usual proprietary lock-in. Microsoft is pushing boundaries here, but let's see how it performs in real-world edge cases. Excited to test it out on some niche datasets! 🚀
On April 7, Microsoft's Bing team announced the open-source release of a new word embedding model series called "Harrier," designed to reshape the underlying logic of global search, retrieval, and AI agents. The Harrier series includes three versions, with the flagship 27B model surpassing major proprietary models from OpenAI, Amazon, and Google Gemini in the multilingual MTEB v2 benchmark, securing the top spot.
The technical foundation of this model reflects strong industrial standards: Harrier supports over 100 languages with a context window of up to 32,000 tokens. For training, Microsoft used over 2 billion real-world examples and incorporated synthetic data from GPT-5 for reinforcement learning. This high-quality data mix gives Harrier a distinct advantage in understanding complex contexts and handling long texts. Alongside the full 27B-parameter version, Microsoft also released smaller 0.6B and 2.7B variants to accommodate different computing environments, all open-sourced on Hugging Face under the MIT license.
Embedding models are essential for organizing and retrieving information in AI systems, and their performance directly impacts the accuracy of RAG (Retrieval-Augmented Generation) systems. Microsoft intends to integrate this technology into the Bing search engine and new AI agent grounding services. As AI moves toward more autonomous, multi-step tasks, the open-sourcing of Harrier not only gives developers a high-performance alternative to proprietary models but also marks a significant milestone for the open-source ecosystem in semantic representation, further accelerating AI agent deployment in multilingual global environments.








 ByteDance’s Seed launches global campus drive, offering virtual shares to win top large model talent
In the competitive landscape of large language models, securing top-tier talent remains the most critical strategic asset.On April 1st, ByteDance announced the launch of its Seed global campus recruitment initiative, part of its large model talent de
 Suno to Watermark Songs Amid Legal Battles
Suno, the platform enabling users to generate AI-created music, has unveiled new features to label platform-produced tracks, restrict downloads, and update community standards to curb unauthorized replicas. These updates arrive as Suno confronts mult
 Musk Admits Grok Build Leaked User Code, Promises to Erase All Historical Data
Elon Musk directly addressed the privacy controversy surrounding Grok Build, beginning with a simple "True" to confirm the incident's validity. He pledged that all user data previously uploaded to SpaceXAI would be permanently erased, stating, "not a

2026 Latest Best AI Visual Style Reference Tools for Character Sheets, Moodboards, and Pitch Decks are here on XIX.AI! This curated top-rated list features powerful game-changing tools that go through rigorous real-world tests. You’ll find a free vs paid comparison, detailed rankings, and must-try options to help you boost creativity and streamline your workflow. Explore now to discover your perfect tool for boosting productivity!
11 tools
xix.ai

2026 Latest Best Top-rated AI SERP Analysis Tools for Search Strategy are curated by XIX.AI through rigorous real-world tests and weekly updated rankings. These powerful tools help you unlock hidden optimization opportunities, boost content performance, and gain a competitive edge in search. Discover your perfect tool to elevate your search strategy today. Explore now!
13 tools
xix.ai

2026 Latest Best Top-rated AI Anomaly Detection Tools for KPI Monitoring in SaaS and Ecommerce teams! XIX.AI has curated a powerful, game-changing collection based on rigorous real-world tests and weekly updated rankings. You’ll find detailed free vs paid comparison insights to help you identify the must-try solution that boosts productivity and unlocks your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Outline Generators for Long-Form SEO Articles, meticulously curated by XIX.AI. These powerful tools offer game-changing assistance in creating high-quality content quickly, boosting writing efficiency significantly. Get a free vs paid comparison along with real-world tests and detailed rankings to help you find the must-try option that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI Study Tools for Homework and Exam Prep! XIX.AI curates a top-rated list of powerful, game-changing tools that help students boost productivity, streamline homework completion, and ace exams through real-world tests. Get a free vs paid comparison, detailed rankings, and must-try options to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

Finally, an open-source embedding model that actually challenges the big players! Harrier's 27B parameters look promising for multilingual tasks, especially if it improves retrieval accuracy without the usual proprietary lock-in. Microsoft is pushing boundaries here, but let's see how it performs in real-world edge cases. Excited to test it out on some niche datasets! 🚀












