option
Home
Flash News
Content
WalterMartinez
WalterMartinez
September 18, 2026

Zhipu launched GLM-5.3-FlashX, a high-speed AI model delivering 200 tokens per second. Built on the popular GLM-5.3-Flash, it leverages 100,000 domestic chips for optimized inference. This update balances intelligence, cost, and speed, significantly accelerating enterprise developer experiences while maintaining the superior performance of its predecessor.
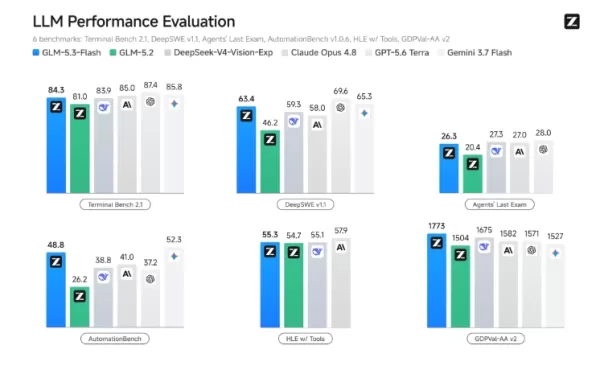
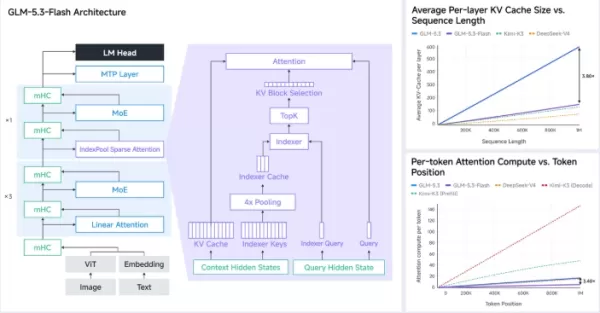
Zhipu launched GLM-5.3-FlashX, a high-speed AI model delivering 200 tokens per second. Built on the popular GLM-5.3-Flash, it leverages 100,000 domestic chips for optimized inference. This update balances intelligence, cost, and speed, significantly accelerating enterprise developer experiences while maintaining the superior performance of its predecessor. Zhipu launched GLM-5.3-FlashX, a high-speed AI model delivering 200 tokens per second. Built on the popular GLM-5.3-Flash, it leverages 100,000 domestic chips for optimized inference. This update balances intelligence, cost, and speed, significantly accelerating enterprise developer experiences while maintaining the superior performance of its predecessor.
Comments (0)
0/300
OR